Journal
Sections
Reading settings
No voice for this language in this browser.
More voices
Code and English terms
Off: the page’s voice reads everything, with no pause between two voices.
No voice for this language in this browser.
More voices
More voices: Microsoft Edge has natural online voices, and Windows (Settings › Time & language › Speech), macOS and Android install others.
Progress
Section titled “Progress”- ComfyUI v0.36.0 (commit
ee71d5c), frontend 1.52.7, SDXL base 1.0 pinned by file hash -
check.sh: offline workflow checks, UI-to-API conversion compared with the frontend’s export, the C# and Java clients against ComfyUI on the CPU - CI on Ubuntu, Windows and macOS, without a GPU or a model
- Lesson 1: the node graph, installing, and a first image
- Lesson 2: diffusion, and what makes an image reproducible
- Lesson 3: workflows as JSON
- Lesson 4: the HTTP and WebSocket API from C# and Java
- French and Spanish translations of lessons 1 to 4
- Lesson 5: img2img, inpainting and outpainting
- Lesson 6: ControlNet, edges and depth
- Lesson 7: LoRA
- Lesson 8: recent models, licenses, quantization and VRAM
- French and Spanish translations of lessons 5 to 8
- Lesson 9: upscaling, seamless textures and HDR
- Lesson 10: video
- Lesson 11: custom nodes, and their security
- Lesson 12: ComfyUI in production
- Lesson 15: audio, read in the source
- A “Your turn” section on every written lesson, and a gallery of the thirty images
- Lesson 13: textures for this site and for GuitarAlchemist
- Lesson 14: the Guitar Alchemist lab
What this course found in ComfyUI v0.36.0, in its documentation and in the files it loads, by running them rather than reading about them. Source links point at ee71d5c, the commit the course pins. None of these is an issue report yet: it is what the measurements showed.
| Expected | What happens | Where | Measurement | Status |
|---|---|---|---|---|
| A fresh base directory starts the server | Startup stops with FileNotFoundError: the server lists custom_nodes in the new directory before anything creates it |
main.py:198-201 |
Reproduced at every fresh base directory | Reproduced; server.sh creates the empty folder first |
--base-directory leaves the installation alone |
It migrated the installation’s legacy user/comfyui.db, left a .bak beside it and copied the database into the test directory |
--base-directory without --database-url |
The original was restored from the backup; both SHA-256 matched | Reproduced; avoided with --database-url sqlite:///:memory: (ComfyUI preflight for the orbital scene) |
The getting-started tutorial describes EmptyLatentImage |
It says the node makes a noise latent. The node makes zeros, and KSampler makes the noise |
nodes.py, against the text-to-image tutorial |
Read in the node’s code at the pinned commit | Reproduced. The documentation is wrong, the behaviour is right |
| The same graph and seed give the same pixels | The image changes when the negative prompt is encoded again with the UNet already loaded | nodes.py, CLIPTextEncode and KSampler |
698e7867… on a fresh server, 5374ac40… warm: 0.92 levels of mean difference, 2.63 % of pixels above 8. --deterministic changed neither |
Reproduced. The operation responsible is still unidentified (One seed, two images) |
| An image in a batch equals the same seed rendered alone | The batch’s first image differs from the single render | nodes.py, EmptyLatentImage and KSampler |
0.74 levels of mean difference | Reproduced |
| Validation lists every problem of a prompt | A link to a missing node raises a KeyError outside the try block, and the server answers with a traceback carrying its installation path |
execution.py:932-933 |
The server reported 2 errors where the offline check found 5; one was filed under node 3 with node 8’s input name, samples |
Reproduced |
| The PNG records what the client sent | Validation converts every FLOAT input with float() and writes the value back into the prompt that is saved |
execution.py:995-997 |
The frontend sent 7 for cfg; the prompt inside the PNG holds "cfg": 7.0 |
Reproduced. Harmless to the image, and enough to break a byte-for-byte comparison of two prompts |
| Output nodes run in a stable order | Validated outputs are kept in a Python set, whose iteration order follows the randomized string hash | execution.py:1186-1282 |
check.sh failed on its second run: the two SaveImage nodes ran in the other order |
Reproduced; fixed in the course with PYTHONHASHSEED=0 |
POST /upload/image has documented behaviour |
Identical bytes keep the existing name; different bytes get name (1).png |
server.py |
Both observed; neither is documented | Reproduced. The documentation is silent |
SetUnionControlNetType’s page lists the types the node has |
The page lists 13 types, the node has 8 | nodes_controlnet.py, against its documentation |
The 8 names were read in the node’s code | Reproduced. Take the names from the code |
| A LoRA’s metadata describes its tensors | LCM-LoRA’s metadata and its title say rank 1 and alpha 1 | sdxl_LCM_lora_rank1.safetensors |
Its tensors give rank 64 and alpha 8 | Reproduced. The file’s metadata is wrong; read the tensors (Models for lessons 5 to 8) |
| A quantized file’s name says what is inside it | qwen_3_4b_fp8_mixed holds 12 nvfp4 layers, and qwen_3_4b_fp4_mixed holds 58 fp8 layers |
Comfy-Org’s Z-Image-Turbo text encoders | Counted in the headers | Reproduced. “mixed” is the warning: read the header |
nvidia-smi shows what a model needs |
Dynamic VRAM takes what is free, so the figure says nothing about the model | --disable-dynamic-vram and the staging lines of the log |
12.5 to 15.3 GB in use for every configuration, from 19.4 GB of bf16 weights down to nvfp4 | Reproduced. The staged sizes in the log are the useful numbers |
| The API documentation lists the routes the server serves | The /api/jobs routes, the /api prefix on every route and the binary preview messages are missing from it |
server.py |
Read in the routing table at the pinned commit | Reproduced. The documentation is incomplete |
execution_success means the run can be read in /history |
It is sent before the history is written. The same prompt_id posted twice runs twice and overwrites its entry, and a reconnection replays nothing |
execution.py, server.py |
Each case was provoked on a CPU server and its answers recorded | Reproduced; handled in the course’s worker (ComfyUI in production) |
LoadImage lists the files the server can read |
It lists the files whose MIME type starts with image, and that table belongs to the machine, not to ComfyUI |
folder_paths.py |
.exr has no MIME type on this Windows machine and on the macos-latest runner, and is image/aces on ubuntu-latest, all with Python 3.13 |
Reproduced on three machines by data/mime-info.py. An EXR written by SaveImageAdvanced cannot be picked from the list on two of the three |
| A repackage’s licence covers the files it ships | Comfy-Org/TRELLIS.2 is tagged MIT and ships clip_vision/dino_v3_vit_l.safetensors, which is under the DINOv3 licence, without a copy of that licence |
The repository’s file tree | Read on the model card and in the tree | Reproduced. A repackage does not change a file’s licence. This is not legal advice |
| A model’s licence governs what you do with the weights | The Hunyuan 3D 2.0 licence also restricts where its outputs may be displayed: clause 5.c, Territory excluding the European Union, the United Kingdom and South Korea | Clauses 1.l and 5.c, read at commit 9cd649ba |
Two renders had already been published on this site, and were removed | Reproduced. The course publishes no Hunyuan3D output (A 3D model published before its license was read) |
| A node that prepares an inpainting latent leaves the pixels alone | VAEEncodeForInpaint pushes every masked pixel to mid grey before encoding, which the inpainting tutorial does not mention |
nodes.py:443-447 |
At denoise 0.5 the masked area came back a flat grey ellipse; denoise 1 with a 24-pixel soft edge, or the inpainting UNet, gives a usable result |
Reproduced. The node is built for denoise 1 |
| A LoRA’s card describes the file it ships | Pixel Art XL is published under CreativeML Open RAIL-M, not the RAIL++-M of the SDXL it extends, and its card says no trigger word is needed while the file’s header sets instance_prompt: pixel art |
nerijs/pixel-art-xl at 8bf4a4d9 |
Licence read on the card at download time, instance_prompt read in the safetensors header |
Reproduced. Read the header, not the card |
| Something inspects a custom-node pack before it runs | Nothing does. Each pack is imported with exec_module before its NODE_CLASS_MAPPINGS is read, a prestartup_script.py runs earlier still, and a pack’s WEB_DIRECTORY JavaScript runs in the browser |
nodes.py:2266 |
comfyui_manager 4.2.2 gates installs by security level, listener and two flags and matches known bad package names at startup; no step reads a pack’s code. The 42 files of its PyPI wheel were identical to the 4.2.2 tag, commit bd4ede22 |
Reproduced. Installing a pack is running its code |
| Loading a checkpoint does not execute code | A pickle whose payload calls print ran under pickle.loads and under torch.load(weights_only=False); torch.load(weights_only=True) refused it on PyTorch 2.13 |
comfyui_controlnet_aux, pinned 16 September 2026 — a pack, not ComfyUI core |
72 torch.load calls without weights_only, which defaults to safe only on PyTorch 2.6 and later |
Reproduced |
| Installing a pack is the only step that reaches the network | ComfyUI-Impact-Pack pip-installs onnxruntime the first time an ONNX detector runs, and its install.py downloads a SAM .pth; rgthree-comfy sends a model file’s SHA-256 to Civitai when the interface asks for that model’s information |
ComfyUI-Impact-Pack/install.py and rgthree-comfy, both pinned 16 September 2026 |
Audit of six packs: ComfyUI-GGUF, comfyui_controlnet_aux, ComfyUI-Impact-Pack, ComfyUI-VideoHelperSuite, rgthree-comfy, ComfyUI_essentials | Reproduced. None of it suggests bad intent; it is what a pack may do without saying so |
| The sample client’s stop condition says the run went well | websockets_api_example.py breaks on an executing message whose node is null, which says only that nothing is running any more — not whether the run succeeded, failed or was interrupted |
script_examples/websockets_api_example.py:37-40 |
That message is sent after the history is written, unlike execution_success, so reading the results afterwards is safe; the course’s clients stop on execution_success, execution_error or execution_interrupted instead |
Not a defect, and too coarse for a worker: a failed run has to be told apart from a finished one |
| A fully cached run reports only what it did | It sends executed for each output node, carrying the first run’s file names, and writes no file |
comfy_execution/asset_enrichment.py:102-115 |
On a re-queued identical prompt, the cache hit at execution.py:446-451 calls emit_cached_output, which sends the message with the cached output |
Reproduced. A client that counts executed messages, or trusts their file names, will believe files were written |
/object_info lists a node’s inputs under required and optional |
A COMFY_DYNAMICCOMBO_V3 input carries its children inside its options, so SaveVideo’s format.codec is in neither map |
/object_info for SaveVideo, v0.36.0 |
The course’s own checker reported “no input format.codec” on three workflows and was wrong |
Not a defect: the shape is deliberate and the documentation is silent about it. The bug was ours (A workflow checked before the GPU) |
QUANTIZATION.md points at the code it describes |
It gives MixedPrecisionOps as “lines 542-648 in comfy/ops.py”; the class is at line 1347, and it is nested inside the factory mixed_precision_ops() rather than being a module-level class |
QUANTIZATION.md:83 against comfy/ops.py:1346-1347 |
Line 542 holds self.weight_comfy_model_dtype = dtype, unrelated |
Reproduced at the pinned commit (Four findings that never left the report) |
| The API-format page describes the UI format’s node keys | Its table gives “Node titles or labels” for the save format against “Numeric node IDs” for the API format; both identify nodes by id | the workflow API format page, read 22 September 2026 | 01-txt2img.ui.json holds nodes as a list of 7 objects, each with a numeric id, none with a title, and links refers to those numbers |
Reproduced. The difference is an array against an object keyed by the id, not titles against ids (Four findings that never left the report) |
--lowvram keeps less of a model resident than the default |
It sets VRAMState.LOW_VRAM, but the partial-load budget takes one branch for LOW_VRAM and NORMAL_VRAM alike and computes the same amount from free memory |
comfy/model_management.py:1007-1011 |
The 16 September renders measured no difference between the flag and the default; --novram does differ, pinning the budget to 0.1 |
Reproduced (Four findings that never left the report) |
| A CLI sends its commands where the command line says | comfy-cli auto-detects the target: cloud if any cloud credential is configured — an API key or an active OAuth session — else local. Signing in once changes where later commands go | comfy_cli/where.py, read 22 September 2026 on main; comfy-cli is not pinned by this course |
The precedence is set out in the module’s own docstring, rule 5 | Reproduced. Worth knowing before a script runs against something other than localhost (Four findings that never left the report) |
Experiments
Section titled “Experiments”One row per measured experiment. The hypothesis column says what was predicted before the number existed; where the course measured first and understood afterwards, it says so rather than inventing a prediction that would have known the answer.
| Question | Hypothesis | Measured result | Verdict | Evidence |
|---|---|---|---|---|
Does denoise below 1 shorten the run? |
Not written in advance. What was being tested is the reading the word invites: fewer steps for less denoising | 25 steps ran at every value from 0.3 to 0.9, in 4.6 to 5.1 s | Refuted: denoise starts the sampler partway down a schedule of the same length |
Img2img, inpainting, ControlNet and LoRA, 05-img2img.api.json |
| Do the two seed-42 images come from dynamic VRAM staging? | Written before the run: disabling dynamic VRAM should bring back the cold-start pixels | --disable-dynamic-vram gave the warm hash 5374ac40… on the first run, and the same pixels as dynamic VRAM, in 78.87 s against 63.93 |
Inconclusive: the hypothesis failed and the operation responsible is still unknown | One seed, two images, Recent models and quantization |
Does the SD-XL inpainting model need strength below 1.0, as its card says? |
The card’s instruction stood as the prediction | 1.0 and 0.99 differ on 0.01 % of the pixels by more than 8 levels | Refuted on this image; one image is not a general answer | Img2img, inpainting, ControlNet and LoRA, 05-inpaint-model.api.json |
| What does quantization cost in image, and buy in speed? | Not written in advance | int8 with the fp8 encoder: 9 to 15 % of pixels differ from bf16 by more than 8, at 3.1 steps per second against 1.5. nvfp4 with fp4: 62 to 74 %, at 3.7 to 4.1 | Confirmed for int8, refuted for nvfp4: it is not a degraded image but another arrangement of the same scene | Recent models and quantization, 08-z-image-turbo.api.json |
| Is a ControlNet still needed after the first steps? | Written in the lesson before the render: the layout is decided early, so end_percent 0.3 should keep the composition |
The ControlNet guided 8 of 25 steps, and the image was almost the same as with it on throughout | Confirmed | Img2img, inpainting, ControlNet and LoRA, 06-canny.api.json |
| Does a LoRA slow sampling down? | Not written in advance. The assumption under test is that added weights cost time at every step | Switching LoRAs cost 4 to 5 s before the first step; a 4-step LCM-LoRA image then took 1.16 s | Refuted: the patch is computed once, when the model is loaded | Img2img, inpainting, ControlNet and LoRA, 07-lcm.api.json |
| Does a wider cross remove the seam of an offset-and-repainted texture? | Written after the first failure and before the second run: 384 pixels of cross, 128 of feather and denoise 1 would close it | The 160-pixel cross halved the seam, 13.4 to 5.2 levels at the middle row, but left a speckled line and a step in tone. The wide cross removed the line; the step in tone stayed | Confirmed, with a reservation: the seam is gone, the tone difference between halves is not | Upscaling, seamless textures and HDR, 09-seamless.api.json |
| Is a 16-bit PNG or an EXR of a render actually HDR? | Not written in advance. The expectation under test is that a wider container carries more | 256 levels per channel in the 16-bit PNG of an 8-bit render, and no value above 1.0 in the EXR: the VAE clamps its output to 0 to 1 | Refuted: the container is HDR, the content is not | Upscaling, seamless textures and HDR, 09-exr.api.json |
| Does tiled VAE decoding change the image? | Not written in advance | 0.93 levels of mean difference at 2048 × 2048, where a plain decode also fit on the GPU | Confirmed: small, and not nil — decode plainly when it fits | Upscaling, seamless textures and HDR, 09-hires-fix.api.json |
Is the Canny node’s output comparable across machines? |
Written before CI ran: an edge filter with integer-looking output should give the same pixels everywhere | Four machines gave four pixel hashes; the three CI runners found 467 edge pixels, the author’s machine 464 | Refuted: it is floating-point code. CI prints the numbers as information instead of comparing them | Img2img, inpainting, ControlNet and LoRA, check.sh |
Which step of Kornia’s canny stops agreeing between machines? |
Not written in advance: the lesson asked for the step without naming one | The input is identical on four machines; the Gaussian blur separates three groups, the spatial gradient all four, every magnitude differs — and the thresholded edges are identical, 1,461 pixels of 3,072 | Answered, in two halves: the divergence starts at the first convolution and is always there; it reaches the output only when pixels sit near a threshold | data/canny-steps.py, lesson 6 |
What does the convrot flag of an int8 checkpoint do? |
Written in lesson 8 before the kernel was read: a rotation of groups of weights before quantizing, to spread large values so that one scale fits them better | comfy-kitchen 0.2.34 rotates each group of 256 input channels by a regular Hadamard matrix, symmetric and orthogonal: the weight offline, the activations online. On a weight with one outlier per row, the int8 round-trip error is 5.7 % plain and 0.76 % rotated | Confirmed, with a number. Being its own inverse, the matrix leaves the product alone; it only changes what int8 has to hold | data/convrot.py, lesson 8 |
| What does a cold start cost against a warm one? | Not written in advance. The assumption under test is that a render’s time is its sampling time | The first SDXL render took 14.71 s, of which about 4 s were the 25 steps at 6.4 steps per second; with the models loaded, a new seed took 4.6 s | About ten seconds of a first render is loading, not sampling | First renders, 01-txt2img.api.json |
| What do latent previews cost? | Not written in advance. The assumption under test is that decoding a preview alongside sampling is negligible | --preview-method taesd took sampling from 6.4 to 4.9 steps per second, about 23 % |
A preview is not free; it is paid in sampling speed | First renders, 01-txt2img.api.json |
| Does inpainting leave the unmasked pixels alone? | Not written in advance. The assumption under test is that a mask confines the change to the masked region | The decoded result changed 6.2 % of the pixels outside the mask by more than 8 levels; pasting it back with ImageCompositeMasked left them identical |
Refuted: the VAE round trip touches the whole image, and the paste-back is what preserves it | Img2img, inpainting, ControlNet and LoRA, 05-inpaint-model.api.json |
| Does one prompt transfer to another model? | Not written in advance. The assumption under test is that a prompt tuned on one model carries to a newer one | FLUX.2 klein 4B drew a brass stand, not a metronome, on seeds 42, 43 and 44 — 0 of 3; Z-Image-Turbo drew a metronome 3 of 3 | Refuted: the same words are not the same instruction to two models | Recent models and quantization, 08-flux2-klein.api.json |
| How does a sampling step scale with resolution? | Not written in advance. The assumption under test is that the cost tracks the pixel count | About 0.3 s per step at 1024 × 1024, and 2.2 to 2.8 s at 2048 × 2048 — 7 to 9 times the cost for 4 times the pixels | Worse than linear in pixel count, which is the reason the hires fix exists | Upscaling, seamless textures and HDR, 09-hires-fix.api.json |
| What does a well-behaved custom-node pack cost to load and run? | Prior for one half only: the flags were checked against code read beforehand. For the timings, Not written in advance. The assumption under test is that a pure-Python pack costs nothing measurable | On the CPU, in a throwaway base directory: the pack imported in 0.0 s and ran in 0.06 s, SaveImage wrote the same pixels as the test’s expected PNG, and 14 unit tests passed with only NumPy and Pillow |
Confirmed on both halves: the flags behave as the source says, and the cost is below what the clock shows | Custom nodes and their security |
| Can 26 workflows be validated with no GPU and no model? | Not written in advance. The assumption under test is that a workflow cannot be checked before the memory exists to run it | A model-free ComfyUI on the CPU gave its /object_info — 957 node classes, 1.85 MB — and all 26 workflows check out against it. The check first reported that SaveVideo has no input format.codec on three of them, and was wrong: the bug was in the course’s own validator |
Confirmed: lesson 10 can be run the moment the memory is there | A workflow checked before the GPU, check.sh |
2026-09-16 — Versions and setup
Section titled “2026-09-16 — Versions and setup”- ComfyUI v0.36.0 was released the day before, on 15 September 2026, and is the latest release; its tag points at commit
ee71d5c. The Windows portable build for NVIDIA is 1,917,442,353 bytes and ships Python 3.13.14 and PyTorch 2.13.0 for CUDA 13.0. - The course reuses a portable build already installed on the machine, and never writes into it: the server starts with
--base-directorypointing elsewhere,--models-directorypointing at the install’s models, and--database-url sqlite:///:memory:. - A fresh base directory made the server stop at startup with
FileNotFoundError, because it listscustom_nodesbefore creating anything.server.shcreates the empty folder. sd_xl_base_1.0.safetensorson the machine has the SHA-256 that Hugging Face lists,31e35c80…7e5b.- The documentation’s getting-started pages and API examples use Stable Diffusion 1.5 at 512 × 512, not SDXL. The manual install page uses conda;
venvonly appears on the comfy-cli page. The text-to-image tutorial saysEmptyLatentImagemakes a noise latent; it makes zeros, andKSamplermakes the noise.
2026-09-16 — First renders
Section titled “2026-09-16 — First renders”- The first SDXL render took 14.71 seconds, of which about 4 were the 25 sampling steps at 6.4 steps per second. With the models loaded, a new seed took 4.6 seconds.
- The prompt asked for a brass metronome; seed 42 drew something like an hourglass. Seed 43 came closer.
nvidia-smishowed about 7 GB more in use during rendering. The log staged 1,560 MB for the text encoders, 4,896 MB for the UNet, and 159 MB for the VAE.- The latent previews of
--preview-method taesdslowed sampling from 6.4 to 4.9 steps per second.
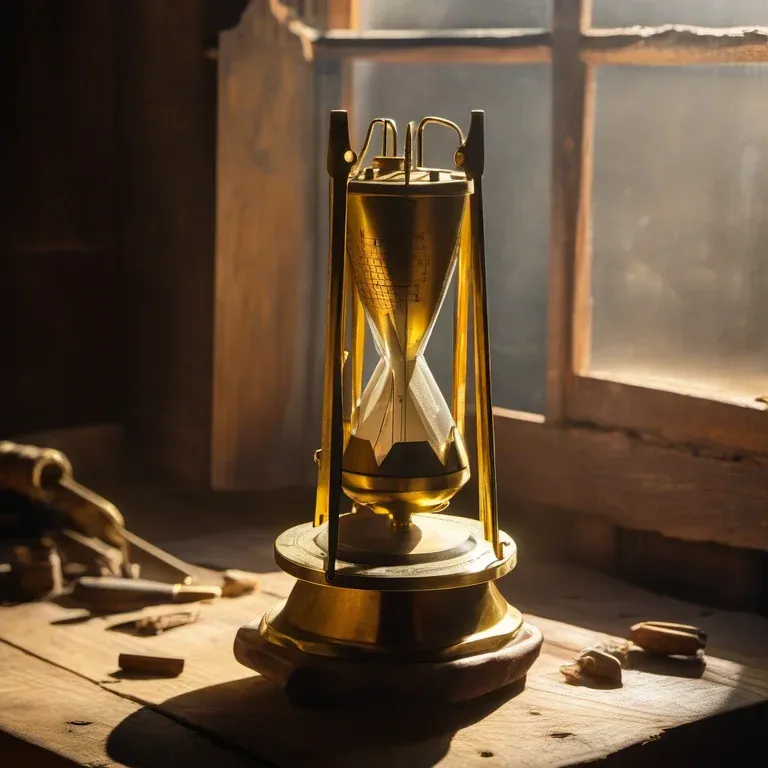
The first render. ComfyUI v0.36.0: Stable Diffusion XL base 1.0, seed 42, 25 steps, euler, normal, CFG 7, 1024 × 1024, workflow 01-txt2img.api.json.
2026-09-16 — One seed, two images
Section titled “2026-09-16 — One seed, two images”- The same workflow and seed gave
698e7867…on a freshly started server, again after restarts, and5374ac40…whenever the negative prompt was encoded again with the UNet already loaded. The two images differ by a mean of 0.92 levels, and 2.63 % of the pixels differ by more than 8. --disable-dynamic-vramgave5374ac40…on the first run too.--deterministicchanged neither result. I haven’t found which operation differs.- The first image of a batch of two differed from the single image with the same seed (mean 0.74), and the second image of the batch isn’t seed 43’s.
- A seed-43 render by the Java client, on another server start 20 minutes later, had the same pixels as the first seed-43 render.
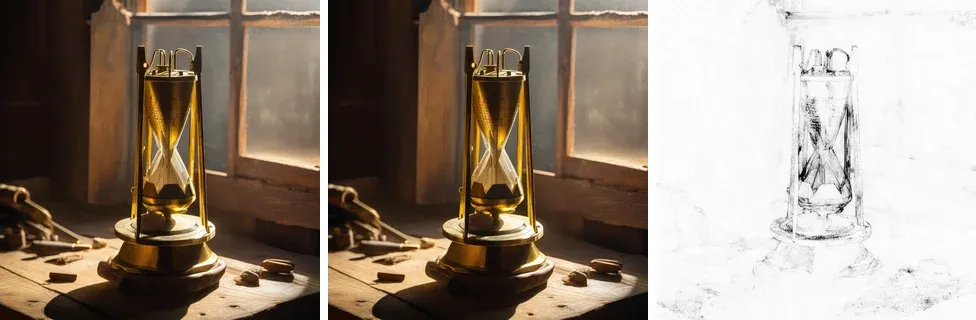
The two seed-42 images. ComfyUI v0.36.0: Stable Diffusion XL base 1.0, seed 42, 25 steps, euler, normal, CFG 7, workflow 01-txt2img.api.json. Left: first run after starting the server. Middle: the same graph after the negative prompt was encoded again. Right: where they differ, amplified eight times.
2026-09-16 — The JSON formats and the API
Section titled “2026-09-16 — The JSON formats and the API”- Loading the API file in the frontend and calling
app.graphToPrompt()gave a UI file and an API export. The C# converter, which reads widget names from/object_info’sinput_orderand skips the seed’s control widget, produces the export byte for byte. - A PNG queued from the browser recorded seed 42 in its
workflowchunk, and the frontend changed the seed to 140956311522585 right after queuing, because itscontrol_after_generatewidget was set torandomize. - The server wrote
"cfg": 7.0into the PNG’s prompt for a frontend that sent7: validation convertsFLOATinputs withfloat()and writes them back. - A link to a missing node made the server’s validation raise a
KeyErroroutside itstryblock. The server reported two errors where the offline check found five; one was filed under node 3 with node 8’s input name,samples, and a traceback that includes the server’s installation path. check.shfailed on its second run: the twoSaveImagenodes ran in the other order. The server keeps validated outputs in a Python set, and string hashes are randomized at each start.server.shnow setsPYTHONHASHSEED=0.- A fully cached run still sends
executedfor each output node, with the first run’s file names, and writes nothing. - The first CI run failed on Ubuntu only: the same 64 × 48 PNG compressed to 84 bytes there and to 88 on Windows and macOS.
png-infonow prints the inflated size. - The Python API example in ComfyUI’s repository waits for
executingwith anullnode. The server sends it after the history is written; the clients stop onexecution_success,execution_errororexecution_interruptedinstead. - The documentation doesn’t list the
/api/jobsroutes, the/apiprefix on every route, or the binary preview messages.
2026-09-16 — Models for lessons 5 to 8
Section titled “2026-09-16 — Models for lessons 5 to 8”- The disk of the course’s machine was nearly full, so the new model files went to another drive, declared to ComfyUI with
--extra-model-paths-config. Each file was downloaded from a pinned Hugging Face revision and checked against the SHA-256 that Hugging Face lists, and its license was read on the model card at the time. - Pixel Art XL is under CreativeML Open RAIL-M, not the RAIL++-M of SDXL. Its card says no trigger word is needed, and its metadata sets
instance_prompt: pixel art. - The LCM-LoRA’s metadata says rank 1 and alpha 1, and its title
sdxl_LCM_lora_rank1; its tensors have rank 64 and alpha 8. - The Qwen3 4B text encoder has the same SHA-256 in Comfy-Org’s Z-Image-Turbo and FLUX.2 klein repositories.
2026-09-16 — Img2img, inpainting, ControlNet and LoRA
Section titled “2026-09-16 — Img2img, inpainting, ControlNet and LoRA”denoisedidn’t change the number of steps: 25 steps ran for every value from 0.3 to 0.9, in 4.6 to 5.1 seconds.- Uploading identical bytes under a taken name returned the existing name; different bytes got
name (1).png. Neither is documented. VAEEncodeForInpaintgrays the masked pixels, which the tutorial doesn’t say. Withdenoise0.5, the result was a flat gray ellipse.
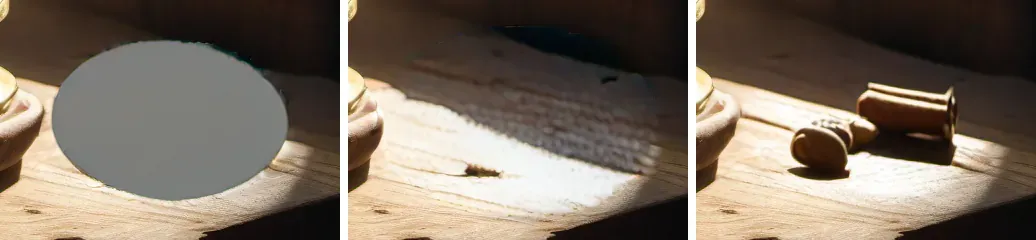
Two inpainting failures and the fix, before pasting back. ComfyUI v0.36.0: Stable Diffusion XL base 1.0, seed 42, 25 steps, CFG 7, euler, normal. From left to right: 05-inpaint-vaeencode.api.json with denoise 0.5; the same workflow with denoise 1 and a mask with a 24-pixel soft edge; 05-inpaint-model.api.json, the SD-XL inpainting 0.1 UNet with denoise 0.99, on the same soft mask.
- The SD-XL inpainting card says to keep
strengthbelow 1.0; 1.0 and 0.99 gave nearly the same image here (0.01 % of the pixels differ by more than 8). - The decoded inpainting result changed 6.2 % of the pixels outside the mask by more than 8 levels; pasting it back with
ImageCompositeMaskedleft them identical. - The documentation page of
SetUnionControlNetTypelists 13 types; the node has 8. - The first CI run of the
Cannynode failed on all three OSes: four machines gave four pixel hashes. The three runners found 467 edge pixels, the author’s machine 464. CI now prints them as information.
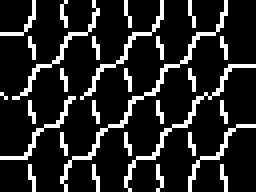
The Canny node’s output on the author’s machine, pixel hash 77af5cb1b7e93a5c, 464 edge pixels, enlarged four times without smoothing. ComfyUI v0.36.0 on the CPU, no model, thresholds 0.05 and 0.15, workflow 05-masks.api.json. The three CI runners each drew 467 edge pixels, with three other hashes.
- With
end_percent0.3, the ControlNet guided 8 of 25 steps, and the image was almost the same as with it on for every step. - A LoRA costs time before the first step, not during sampling: switching LoRAs took 4 to 5 seconds more, and a 4-step LCM-LoRA image then took 1.16 seconds.
2026-09-16 — Recent models and quantization
Section titled “2026-09-16 — Recent models and quantization”- Z-Image-Turbo in bf16 with its bf16 text encoder, 19.4 GB of weights, ran on the 16 GB GPU with dynamic VRAM: 63.93 seconds for the first render, then 5.93 seconds at 1.5 steps per second. int8 with the fp8 text encoder ran at 3.1 steps per second, nvfp4 at 3.7 to 4.1.
nvidia-smishowed 12.5 to 15.3 GB in use for every configuration: dynamic VRAM uses what is free. The staged sizes in the log are the useful numbers.- int8 images stayed close to bf16’s (9 to 15 % of the pixels differ by more than 8); nvfp4 images showed the same scene arranged differently (62 to 74 %).
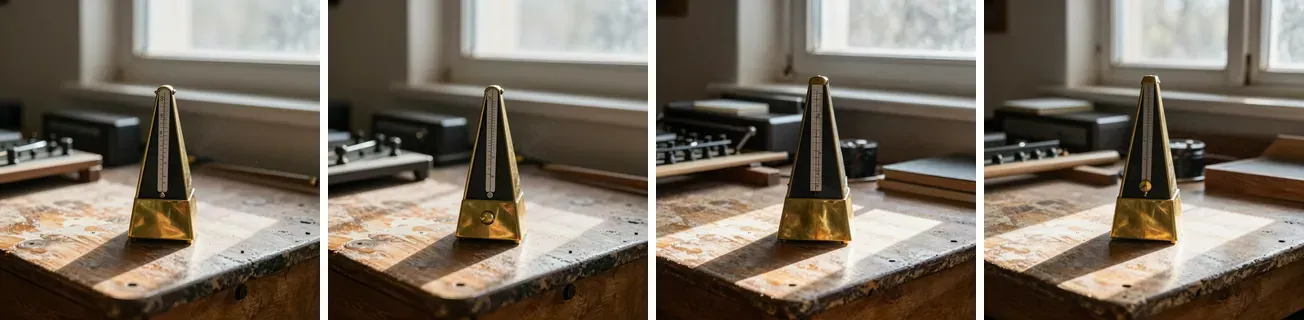
ComfyUI v0.36.0: Z-Image-Turbo, seed 42, 8 steps, CFG 1, res_multistep, simple, workflow 08-z-image-turbo.api.json. From left to right: bf16 with the bf16 text encoder, int8 with fp8, nvfp4 with fp4, nvfp4 with bf16.
qwen_3_4b_fp8_mixedhas 12 nvfp4 layers, andqwen_3_4b_fp4_mixedhas 58 fp8 layers. The nvfp4 Z-Image file keeps its four refiner blocks in bf16.- With
--disable-dynamic-vram, the first bf16 render took 78.87 seconds and gave the same pixels as with dynamic VRAM. The second render was stopped when the machine, shared with other work, ran short of RAM. An earlier bf16 batch had been stopped the same way: the server held 14.5 GB of RAM. Each server now starts only when the configuration’s weights, plus a margin, fit in free RAM. - FLUX.2 klein 4B drew a brass stand, not a metronome, with seeds 42, 43 and 44; Z-Image-Turbo drew a metronome each time.
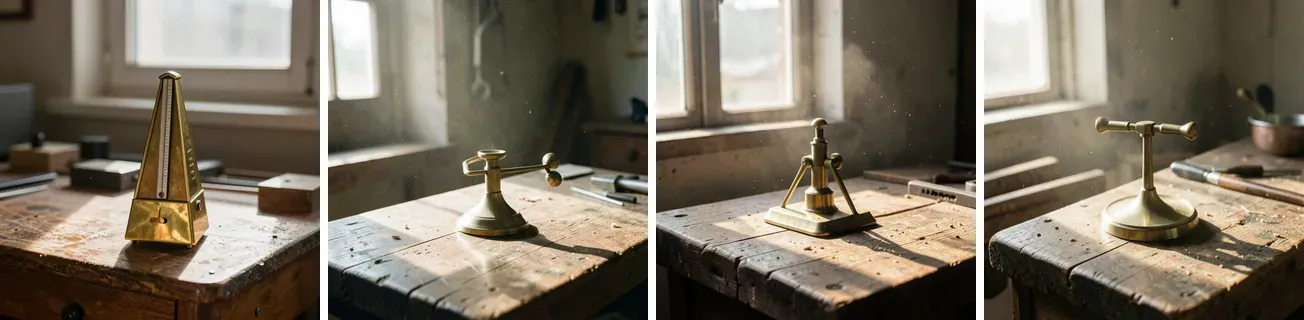
ComfyUI v0.36.0. First: Z-Image-Turbo bf16, seed 43, workflow 08-z-image-turbo.api.json. Then: FLUX.2 klein 4B, seeds 42, 43 and 44, 4 steps, CFG 1, euler, workflow 08-flux2-klein.api.json.
2026-09-16 — Custom nodes and their security
Section titled “2026-09-16 — Custom nodes and their security”- ComfyUI v0.36.0 imports each pack with
exec_modulebefore it readsNODE_CLASS_MAPPINGS;prestartup_script.pyruns earlier, andWEB_DIRECTORYJavaScript runs in the browser.hook_breaker_ac10a0.pyrestores one function after the packs load; nothing else stands between a pack and the process. - ComfyUI-Manager is now the pip package
comfyui_manager==4.2.2, pinned inmanager_requirements.txt. The 42.py,.jsonand.mdfiles of its PyPI wheel are identical to the4.2.2tag, commitbd4ede22. It gates installs by security level, listener and two new flags, and looks for known bad package names at startup; nothing reads a pack’s code. - The Guitar Alchemist pack (GA Chord Diagram, GA Fretboard Control Map, GA Scale Prompt) computes from GA’s tuning and scale tables at
a826864f, draws with Pillow without fonts, and passes 14 unit tests with only NumPy and Pillow. Loaded into a throwaway base directory with the portable build’s Python on the CPU, it imported in 0.0 s, ran in 0.06 s, andSaveImagewrote the same pixels as the test’s expected PNG.--disable-all-custom-nodes,--whitelist-custom-nodes gaand a.disabledfolder behaved as the source says. - The audit script ran on six packs pinned on 16 September 2026: ComfyUI-GGUF, comfyui_controlnet_aux, ComfyUI-Impact-Pack, ComfyUI-VideoHelperSuite, rgthree-comfy and ComfyUI_essentials. None of the findings suggests bad intent. Impact-Pack installs
onnxruntimewith pip the first time an ONNX detector runs, and itsinstall.pydownloads a SAM.pth. rgthree-comfy sends a model file’s SHA-256 to Civitai when the interface asks for its information. comfyui_controlnet_aux has 72torch.loadcalls withoutweights_only, safe by default only on PyTorch 2.6 or later. - A pickle whose payload calls
printran withpickle.loadsand withtorch.load(weights_only=False);torch.load(weights_only=True)refused it on PyTorch 2.13.
2026-09-16 — ComfyUI in production
Section titled “2026-09-16 — ComfyUI in production”- Read in ComfyUI v0.36.0: one
prompt_workerthread runs one prompt at a time; a client may choose aprompt_id, which must be a lowercase UUID; the same id posted twice runs twice and overwrites its history entry;execution_successis sent before the history is written;execution_interruptedis broadcast; a reconnection replays nothing. A recording script provoked these cases on a CPU server and saved the answers. - A worker in C# and in Java with the same log lines: an in-memory queue (a
Channelin C#, aLinkedBlockingQueueand virtual threads in Java) or RabbitMQ, the job id asprompt_id, a claim file anddone.jsonfor idempotency, exponential backoff with full jitter, 400s and ordinary execution errors to the dead letters, out-of-memory errors and 5xx retried, an interrupt on timeout, a GPU pool that picks the server with the fewest prompts ahead, and SIGTERM handling with a grace period. - A fake ComfyUI in ASP.NET Core replays the recorded shapes following a script of failures. 11 xUnit tests and 9 JUnit tests pass, and both workers print the same transcripts on Windows, Linux and macOS in CI. Against a real ComfyUI on the CPU, the C# worker ran four jobs (one duplicate, one dead letter), and the Java worker, on the same server, found the finished prompts in the history without running them again.
- The first CI run hung on Linux and macOS: the fake servers outlived
kill. They now wait for SIGTERM withPosixSignalRegistration. - The GA lab’s chord-to-neck experiment runs as twenty jobs with a results CSV against the fake server. The RabbitMQ adapters, the deployment notes and a GPU run are still to verify.
2026-09-16 — Models for lessons 9 and 10
Section titled “2026-09-16 — Models for lessons 9 and 10”- Downloaded to the models drive and checked against the SHA-256 of the Hugging Face tree API:
RealESRGAN_x4plus.safetensors(66,857,836 bytes, BSD-3-Clause),film_net_fp16.safetensors(68,882,302 bytes), and for Wan 2.2 TI2V 5B, under Apache 2.0,wan2.2_ti2v_5B_fp16.safetensors(9,999,658,848 bytes),umt5_xxl_fp8_e4m3fn_scaled.safetensors(6,735,906,897 bytes) andwan2.2_vae.safetensors(1,409,400,960 bytes). The 18.1 GB of Wan took 10 minutes. - Comfy-Org’s repackage has no fp8 file of TI2V 5B, only fp16.
2026-09-16 — Upscaling, seamless textures and HDR
Section titled “2026-09-16 — Upscaling, seamless textures and HDR”- The RAM rule chose the model at each server start: Z-Image-Turbo nvfp4 with 22 GB of free RAM, int8 with 24 GB. Free RAM fell to 9 GB during the int8 renders.
- A sampling step took about 0.3 seconds at 1024 × 1024 and 2.2 to 2.8 seconds at 2048 × 2048.
- A plain
VAEDecodeof the 2048 × 2048 latent fit on the GPU; its image differs fromVAEDecodeTiled’s by 0.93 levels on average. - The latent upscale left a noisy grain and doubled strings at denoise 0.3.
SaveImageAdvanced’s 16-bit PNG of an 8-bit render has 256 levels per channel, and its EXR has no value above 1.0. The C# client stopped at the first 16-bit PNG: it now decodes them, and lists EXR and AVIF files by size.- The first seamless attempt, with a 160-pixel cross, 64 pixels of feather and denoise 0.7, halved the seams (13.4 to 5.2 levels at the middle row) but left a speckled line and a step in tone. Denoise 0.9 didn’t help; a 384-pixel cross with 128 pixels of feather did.
- “Pale maple” drew maple leaves carved in the wood. “Pale maple wood, a planed board” drew a board.
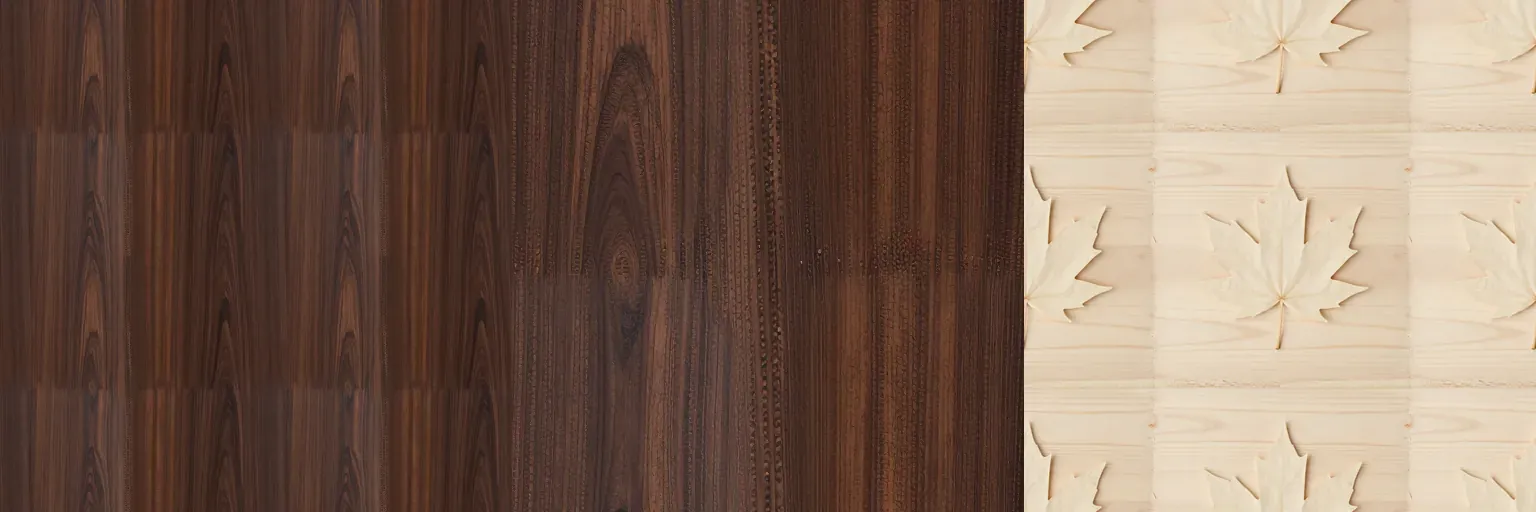
Failures, before the fix. ComfyUI v0.36.0: Z-Image-Turbo nvfp4 with Qwen3 4B fp4 mixed, seed 42, 8 steps, CFG 1, res_multistep, simple, workflow 09-seamless.api.json with its cross set to 160 pixels, 64 of feather and denoise 0.7. From left to right: rosewood repeated 2 × 2; the middle 512 × 512 pixels of the rosewood; the prompt “flat top-down photograph of pale maple, subtle straight grain, even soft lighting, no shadows, wood texture”, repeated 2 × 2.
2026-09-17 — A 3D model published before its license was read
Section titled “2026-09-17 — A 3D model published before its license was read”- On 16 September, the Atlas session generated a metronome and a gramophone as 3D meshes, from SDXL images, with Hunyuan3D 2.0 and ComfyUI’s core nodes. The Blender course’s journal published their renders at 00:23 on 17 September, in commit
a165915. - Reading the license for the GA lab’s image-to-3D experiment, the learn-33 session found clause 5.c of the Tencent Hunyuan 3D 2.0 Community License: “You must not use, reproduce, modify, distribute, or display the Tencent Hunyuan 3D 2.0 Works, Output or results of the Tencent Hunyuan 3D 2.0 Works outside the Territory.” The Territory excludes the European Union, the United Kingdom and South Korea, and this site is public. Our mistake: the renders were published before anyone had read clause 5.c.
- At 00:44 the user decided: Hunyuan3D stays on the local machine, and anything published uses TRELLIS.2 (MIT, with DINOv3 under its own license) or models built with code. The Blender course removed the two renders in commit
c8a5a33and describes in words what they showed. - TRELLIS.2 needs about 23 GB of free RAM here, and upstream asks for 24 GB of VRAM; it hasn’t run. The two objects are being remodelled with
bpyinstead: the Blender journal tells that side of the story, before and after. - Lesson 8 now has a section on reading a license before publishing an output, with the clauses and a comparison of the three routes. No Hunyuan3D image appears in this course.
2026-09-19 — ComfyUI preflight for the orbital scene
Section titled “2026-09-19 — ComfyUI preflight for the orbital scene”A separate CPU server (0.36.0, localhost:8193) confirmed all node classes of the course’s Canny workflow, the installed SDXL checkpoint and union ControlNet. No prompt was submitted; GPU inference remained 0 s. The server was stopped after the check. Unexpectedly, --base-directory alone migrated the installation’s legacy user/comfyui.db to a .bak and copied it into the test directory. The original file was restored from that backup without overwriting another file; both SHA-256 values matched. The backup was retained. Subsequent isolated probes must specify --database-url sqlite:///:memory: or an explicit task-local database URL. Inference and image quality remain to verify.
2026-09-19 — Actual Blender-to-ComfyUI preprocessing
Section titled “2026-09-19 — Actual Blender-to-ComfyUI preprocessing”The Blender v2 render was copied into the isolated ComfyUI input directory. LoadImage → Canny → SaveImage completed successfully on CPU in 3.731 s (history timestamps); the output was visually inspected. Rings, pillars and causeway edges remain visible. This is a control image, not an SDXL-generated scene or new 3D geometry. Prompt ID: 7f26de5e-5d83-455c-97be-1e3401e9ba5f. Output: C:/tmp/blender-comfy-scenes-20260919/comfy-base/output/orbital-study/canny-edges_00001_.png. The explicit in-memory database prevented the previous migration; the installation database hash remained unchanged. GPU time and paid API calls: 0. SDXL inference was deferred rather than loading both models under limited available host RAM (about 10 GiB).
2026-09-22 — A workflow checked before the GPU, and a bug in our own checker
Section titled “2026-09-22 — A workflow checked before the GPU, and a bug in our own checker”- The lesson 10 workflows were written but never run: the machine has not had the free memory for Wan 2.2. Rather than wait, a ComfyUI server was started with no model at all, on the CPU, only to save its
/object_info: 957 node classes, 1.85 MB. The server was stopped straight away. - Against that file, all 26 workflows of the course check out.
Wan22ImageToVideoLatent,CreateVideo,SaveVideo,FrameInterpolationModelLoaderandFrameInterpolateare in the core at v0.36.0,film_net_fp16appears in the loader’s list, and the Wan 2.2 file names are the ones the server sees — so the extra model paths are right. Lesson 10 can be run the moment the memory is there. - The check first reported that
SaveVideohas no inputformat.codec, on all three workflows. It was wrong, and the bug was ours:Workflow.csread only the node’s top-levelrequiredandoptionalinputs, and aCOMFY_DYNAMICCOMBO_V3carries its children inside its options. It now walks them, and checks the option keys too. Lesson 3 has the section, andcheck.sha fixture with three mistakes a dotted input can make. - A validator that has never failed proves nothing. This one now has a file that must fail, and the four new lines of
expected/03-validate.txtare what it must print. - The same day, every written lesson got a “Your turn” section — lesson 9 was the only one that ended with something to do on your own machine — and the thirty images of the course were gathered in a gallery, each with the workflow that made it, at the revision that made it.
2026-09-22 — Where Canny stops agreeing, and what convrot rotates
Section titled “2026-09-22 — Where Canny stops agreeing, and what convrot rotates”- Lesson 6’s open question is answered.
data/canny-steps.pyhashes each step of Kornia’s filter on a 64 by 48 pattern built from integer arithmetic, andcheck.shruns it on the three CI machines. The input is the same bytes everywhere. The Gaussian blur already separates the author’s machine from the runners, and the Apple Silicon runner from the two x86 ones; the spatial gradient differs on all four, although Windows and Linux had agreed one step earlier — the same convolution takes a different path in a different build. Every magnitude differs, and their sum still prints 2729.489258. - The edges, though, are identical on the four machines: 1,461 pixels of 3,072, one hash. This pattern is flat areas and hard borders, so nothing sits near a threshold. That is the other half of the answer — the divergence is always there, from the first convolution; the image decides whether it shows. Lesson 6 has the table.
convrotwas a guess written in lesson 8, “a rotation of groups of weights before quantizing”. comfy-kitchen 0.2.34 confirms it and says which rotation: a regular Hadamard matrix, symmetric and orthogonal, on groups of 256 input channels — the weight offline, the activations online, fused into the row-wise quantizer. Being its own inverse, it leaves the product alone and only changes what int8 must hold.data/convrot.pyrebuilds it, identical to the library’s at group sizes 16, 64 and 256, and measures the round-trip error on a weight with one outlier per row: 5.7 % plain, 0.76 % rotated.- Lesson 9’s EXR bullet gained the consequence that matters for sharing: a workflow built where
.exrhas a MIME type names an image the next machine’s list will not offer. The file stays valid; the run stops being reproducible.
2026-09-22 — Four findings that never left the report, and one that expired
Section titled “2026-09-22 — Four findings that never left the report, and one that expired”Five findings from the first days lived only in the lane’s report, never in this journal, so they could not become rows. Each was re-checked today before being written down. Four hold; one does not.
QUANTIZATION.mdpoints at the wrong lines, and at the wrong shape. It says “TheMixedPrecisionOpsclass (lines 542-648 incomfy/ops.py)”. At the pinned commit the class is declared at line 1347, line 542 isself.weight_comfy_model_dtype = dtype, andMixedPrecisionOpsis not a module-level class at all: it is defined inside the factorymixed_precision_ops()at line 1346, so it cannot be imported by that name.- The API-format page has the UI format’s node keys wrong. Its comparison table gives “Node keys: Node titles or labels” for the save format against “Numeric node IDs” for the API format. The course’s own exported file says otherwise:
01-txt2img.ui.jsonholdsnodesas a list of 7 objects, each with a numericid, none of them carrying atitle, and every entry oflinksrefers to those numbers. Both formats identify nodes by id; what differs is that one is an array and the other an object keyed by the id. --lowvramchanges nothing against the normal state. The flag setsVRAMState.LOW_VRAM, but the partial-load budget takes the same branch forLOW_VRAMand forNORMAL_VRAM, and computes the same amount from free memory in both. The 16 September renders measured no difference; the code says why.--novramis a different matter: it pins the budget to 0.1.- comfy-cli sends commands to Comfy Cloud as soon as a credential exists. Its own
where.pysets out the precedence, and the last rule is an auto-detect: cloud if any cloud credential is configured, an API key or an active OAuth session, else local. Signing in once changes where later commands go, without the command line saying so. Read today onmain; comfy-cli is not pinned by this course. - The one that expired. A note from 16 September said the portable install page announces NVIDIA or CPU only, while v0.36.0 ships AMD and Intel builds. The release does ship four Windows archives — amd, intel, nvidia and nvidia_cu126 — but the page read today documents all three vendors, with a batch file each. Whatever the page said then, it does not say it now, and there is no capture to prove the earlier state. The note is retired rather than published: a documentation complaint with no evidence of the text it complains about is not a finding.
To verify
Section titled “To verify”- SDXL on Linux with CUDA, and on Apple Silicon with MPS: the course’s GPU machine runs Windows; CI only installs the CPU builds.
- Which operation makes the text encoders give different results depending on whether the UNet is loaded, and whether it happens with other GPUs or drivers.
- Whether an ancestral sampler gives the same image on the CPU and on the GPU for a seed: its step noise is drawn on the device.
- Whether a perceptual hash would be stable across the cases of lesson 2.
- ControlNet chains,
start_percent, and the exact step where a percent’s noise level falls, which the lesson computed but didn’t render. - Training a LoRA with ComfyUI’s experimental nodes, and how much of 16 GB it takes for SDXL.
- Stacked LoRAs in the other order: same image, and same pixel hash or not.
- The emulated path for nvfp4 and fp8 on a GPU without their kernels; the course’s machine has an RTX 50 series GPU only.
- Why the nvfp4 Z-Image network sampled faster with the bf16 text encoder than with the fp4 one.
- Sampling tiles from
SplitImageToTileListand merging them withImageMergeTileList: whether seams show at a low denoise. - Whether three.js’s
EXRLoaderreads ComfyUI’s uncompressed EXR in a browser. - How browsers show the HLG AVIF of
SaveImageAdvanced. - Warm render times with
--disable-dynamic-vram, on a machine with enough free RAM. execution_interruptedas the clients print it, andPOST /interruptwith a prompt id: the run to interrupt has to last long enough, which needs a model.
Open questions
Section titled “Open questions”Not measurements waiting to be run — those are above — but decisions this course has not taken.
- Is
LoadImage’s dependence on the machine’s MIME table worth an issue on ComfyUI, or is it working as intended? A call tomimetypes.add_typefor the formats ComfyUI itself writes would fix it in a line, and would change what an existing installation lists. - Which part of two x86 builds of the same PyTorch version makes their convolutions differ — vectorization, threading, or the linear-algebra backend? The step probe shows that they differ from the very first one, not why.
- When should the pin move? Every measurement here is tied to ComfyUI v0.36.0 at one commit, which is what makes the numbers mean something; nothing says what happens to them at v0.37.