7. LoRA: loading, stacking, and what training one involves
Sections
Reading settings
No voice for this language in this browser.
More voices
Code and English terms
Off: the page’s voice reads everything, with no pause between two voices.
No voice for this language in this browser.
More voices
More voices: Microsoft Edge has natural online voices, and Windows (Settings › Time & language › Speech), macOS and Android install others.
Code: the workflows 07-lora.api.json, 07-lcm.api.json, 07-lightning.api.json and 07-lora-stack.api.json; the header reader in csharp/Safetensors.cs.
A checkpoint is several gigabytes of weights. Fine-tuning all of them for a style or a subject makes another checkpoint of the same size. A LoRA stores only a change to some of the weights, in a file that is often a few hundred megabytes, and ComfyUI adds it to the checkpoint when it loads the model. In C# or Java terms it is a plugin that patches the host’s data, not its code.
Low-rank adaptation
Section titled “Low-rank adaptation”LoRA (E. Hu et al., 2021) “freezes the pre-trained model weights and injects trainable rank decomposition matrices into each layer”. For a weight matrix W with n outputs and m inputs, training learns two small matrices instead of a new W: B, n by r, and A, r by m, where r, the rank, is small, such as 32. Their product B·A has the shape of W, and is added to it:
W’ = W + strength × (alpha / r) × B·A
alpha is a number stored in the file for each layer, and strength is the value you set in ComfyUI. For a 1280 by 1280 attention matrix, a rank 32 LoRA stores 2 × 32 × 1280 = 81,920 numbers instead of 1,638,400. Once added, the change costs nothing at sampling time: the paper’s point is “no additional inference latency”.
Reading a LoRA’s header
Section titled “Reading a LoRA’s header”The course’s tool reads the header of a .safetensors file, the JSON that gives each tensor’s name, type and shape, without loading the weights. For a LoRA, it counts the adapted layers from their lora_down matrices, whose first dimension is the rank, and reads the alpha scalars:
> comfy safetensors-info pixel-art-xl.safetensorspixel-art-xl.safetensors: header 311840 bytes, 2166 tensors, 0.17 GB of tensor data  BF16      2166 tensors,   0.17 GBLoRA: 722 adapted layers (722 in the UNet, 0 in the text encoders), rank 32  alpha: 32 (the weight change is scaled by alpha / rank)metadata ss_sd_model_name: sd_xl_base_0.9.safetensorsmetadata ss_base_model_version: sdxl_base_v0-9metadata ss_network_module: networks.lorametadata ss_network_dim: 32metadata ss_network_alpha: 32.0
> comfy safetensors-info lcm_lora_sdxl.safetensorslcm_lora_sdxl.safetensors: header 350920 bytes, 2364 tensors, 0.39 GB of tensor data  F16       2364 tensors,   0.39 GBLoRA: 788 adapted layers (788 in the UNet, 0 in the text encoders), rank 64  alpha: 8 (the weight change is scaled by alpha / rank)metadata ss_base_model_version: sdxl_base_v1-0metadata ss_network_module: networks.lorametadata ss_network_dim: 1metadata ss_network_alpha: 1metadata modelspec.architecture: stable-diffusion-xl-v1-base/lorametadata modelspec.title: sdxl_LCM_lora_rank1
Three things show here that no loader tells you:
- Both LoRAs change only the UNet.
LoraLoader’sstrength_cliphas no effect with them. - The pixel art LoRA was trained on SDXL 0.9, and is used here on 1.0.
- The LCM-LoRA’s metadata says rank 1, alpha 1, and its title says
rank1. The tensors say rank 64, alpha 8: its changes are scaled by 8 / 64 = 0.125. ComfyUI reads the tensors, not the metadata, so the loader isn’t affected, but a tool that trusts the metadata is wrong about this file.
CI can’t download a LoRA, so it runs the same command on two tiny files written by data/tiny-safetensors.py, a LoRA of 2 layers and a quantized layer for lesson 8, and compares the output on the three OSes.
Where ComfyUI applies the patch
Section titled “Where ComfyUI applies the patch”LoraLoader takes the model and the CLIP text encoders from the checkpoint loader, and returns new ones. It reads the file once per node, and keeps it for the next run. It computes no weights. load_lora_for_models maps the file’s names to the model’s layers, clones the model’s patcher, and records the patches with their strength:
lora = comfy.lora_convert.convert_lora(lora)loaded = comfy.lora.load_lora(lora, key_map)if model is not None: new_modelpatcher = model.clone() k = new_modelpatcher.add_patches(loaded, strength_model)The clone shares the weights of the original model. The patches are applied when the sampler needs the model, by calculate_weight in weight_adapter/lora.py, which is the formula above:
if v[2] is not None: alpha = v[2] / mat2.shape[0]else: alpha = 1.0... weight += function(((strength * alpha) * lora_diff).type(weight.dtype))v[2] is the file’s alpha, and mat2.shape[0] the rank. The server’s log shows the count when the model loads, 722 patches for the pixel art LoRA:
Model SDXL prepared for dynamic VRAM loading. 4896MB Staged. 722 patches attached. Force pre-loaded 512 weights: 1197 KB.A file whose names match nothing in the model doesn’t fail. load_lora logs lora key not loaded for each name and goes on: a LoRA for another base model, such as Stable Diffusion 1.5 on SDXL, silently changes nothing. Look for that line, or for 0 patches attached, when a LoRA seems to do nothing.
A style LoRA, at three strengths
Section titled “A style LoRA, at three strengths”Pixel Art XL is a 171 MB LoRA under the CreativeML Open RAIL-M license, the older license of Stable Diffusion 1.x, without the “++” of SDXL’s. Its card is inconsistent: its tips say “No trigger keyword require”, but its metadata sets instance_prompt: pixel art, and its example prompt starts with “pixel art”. The course’s prompt starts with “pixel art” too.
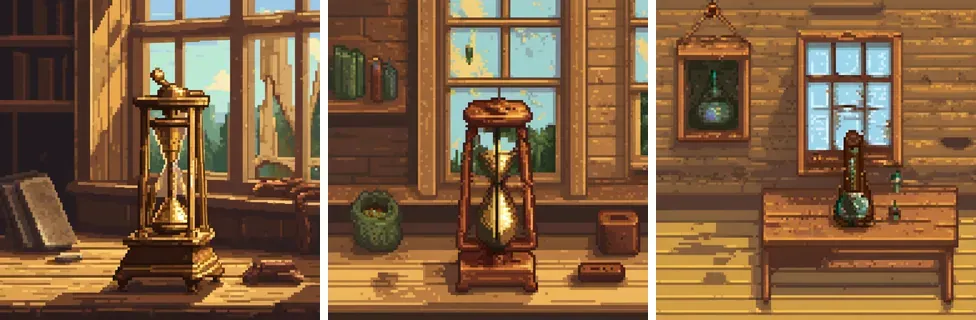
Rendered by ComfyUI v0.36.0: Stable Diffusion XL base 1.0 with Pixel Art XL, seed 42, 25 steps, CFG 7, euler, normal, prompt “pixel art, a brass metronome on an old wooden workbench, morning light through a window”, workflow 07-lora.api.json. From left to right: strength_model and strength_clip 0.5, 1.0 and 1.5.
The LoRA’s strength is a dial between the checkpoint and the style, and both ends lose something. At 0.5 the object is still there, with the base model’s detail drawn in small pixels. At 1.5 the pixels are large and flat, and the subject is gone: the patched weights no longer follow the prompt. The strength inputs go from −100 to 100, and the LoraLoader page says values are “typically used between 0~1 for daily image generation”.
Fewer steps: LCM-LoRA and SDXL-Lightning
Section titled “Fewer steps: LCM-LoRA and SDXL-Lightning”Some LoRAs change how the model samples instead of what it draws. Both of these are distilled: trained so that the model reaches a clean image in a few large steps, as a teacher running many small steps would.
| LoRA | Paper | Size | License | Settings from the card |
|---|---|---|---|---|
| LCM-LoRA SDXL | arXiv 2311.05556 | 394 MB | CreativeML Open RAIL++-M | “only between 2 - 8 steps”, guidance “between 1.0 and 2.0” |
| SDXL-Lightning 4-step | arXiv 2402.13929 | 394 MB | CreativeML Open RAIL++-M | “Euler sampler with sgm_uniform scheduler”, CFG 0 in diffusers |
The model cards give their settings for the diffusers library. In diffusers, guidance 0 or 1 turns classifier-free guidance off; in ComfyUI, CFG 1 does, and the sampler then skips the negative prompt’s pass (lesson 2). The workflows use 4 steps and CFG 1, the lcm sampler for LCM-LoRA, and euler for Lightning, both with the sgm_uniform scheduler. The Lightning card also says to use its full checkpoint rather than the LoRA on SDXL base: “Use LoRA only if you are using non-SDXL base models.”
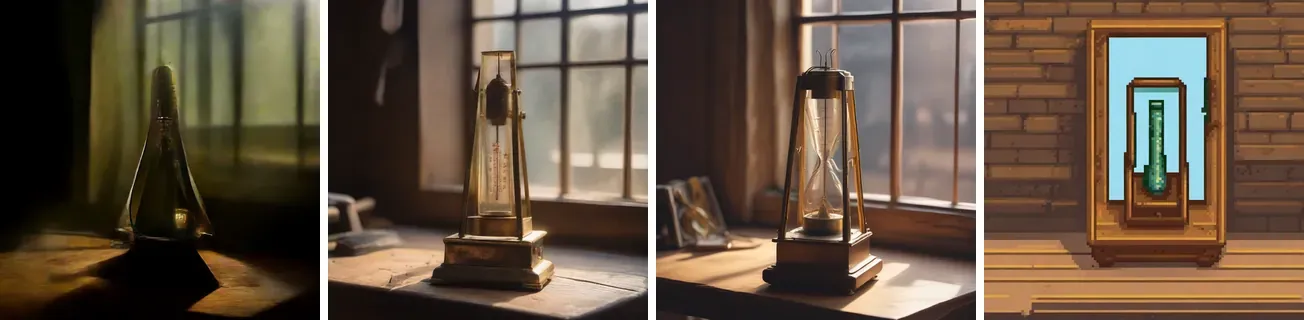
Rendered by ComfyUI v0.36.0: Stable Diffusion XL base 1.0, seed 42, prompt “a brass metronome on an old wooden workbench, morning light through a window, dust in the air, photograph” for the first three. From left to right: 01-txt2img.api.json with 4 steps, CFG 7, euler, normal and no LoRA; 07-lcm.api.json, LCM-LoRA, 4 steps, CFG 1, lcm, sgm_uniform; 07-lightning.api.json, SDXL-Lightning 4-step LoRA, 4 steps, CFG 1, euler, sgm_uniform; 07-lora-stack.api.json, LCM-LoRA at 1.0 and Pixel Art XL at 1.2, 8 steps, CFG 1.5, lcm, sgm_uniform, prompt “pixel art, a brass metronome on an old wooden workbench, morning light through a window”.
The base model with 4 steps stopped far from a clean image, as lesson 2’s step comparison showed. Both LoRAs gave a sharp image in the same 4 steps. Neither drew a recognizable metronome, but the base model doesn’t either with this prompt: lesson 1’s image, with 25 steps, is closer to an hourglass.
A stack of two
Section titled “A stack of two”LoraLoader returns a model, and another LoraLoader can take it: the node’s description says “Multiple LoRA nodes can be linked together.” The second loader clones the patcher again, and adds its own patches to the same layers. When the weights are computed, each patch adds its term to W, so for plain LoRAs the result is
W’ = W + s₁ × (α₁ / r₁) × B₁·A₁ + s₂ × (α₂ / r₂) × B₂·A₂
and the order of the loaders doesn’t change it. The last image above stacks LCM-LoRA and Pixel Art XL with the settings from the Pixel Art XL card: “Use 8 steps and guidance scale of 1.5” and “1.2 Lora strength for the Pixel Art XL works better”. The log said 788 patches attached, not 722 + 788: the pixel art LoRA’s 722 layers are among the LCM-LoRA’s 788, and each layer’s patches count once.
What the patches cost
Section titled “What the patches cost”One server, started fresh, ran these in order. The times are the server’s “Prompt executed” lines, and each “new seed” run changed only the seed, so the text encoders’ results came from the cache:
| Run | Steps | First run | New seed |
|---|---|---|---|
| SDXL base, no LoRA | 25 | 13.49 s, loading the checkpoint | 4.93 s |
| LCM-LoRA | 4 | 6.42 s | 1.16 s |
| SDXL-Lightning LoRA | 4 | 7.40 s | 1.09 s |
| LCM-LoRA again, after Lightning | 4 | 5.37 s |
Switching LoRAs cost about 4 to 5 seconds on the first run: reading the 394 MB file from disk and computing 788 patched layers. After that, a 4-step image took just over a second, against 4.9 seconds for 25 steps without a LoRA: the patch costs nothing per step, and the saving is the steps. Going back to LCM-LoRA paid the cost again, because LoraLoader keeps only the last file it read, and the patches were computed again. nvidia-smi showed the same peak memory with and without a LoRA, about 12.2 GB on a card where 2.7 GB were already in use.
The sampler’s own speed confirms it. In the progress bars of an earlier batch on the same machine, the 25 steps of the pixel art renders ran at 5.5 to 5.9 steps per second, as fast as without a LoRA. The time went into the progress bar’s Model Initializing phase before the first step: 2.4 to 4.9 seconds with the pixel art LoRA, 19.3 seconds the first time Lightning’s file was read from disk.
Training a LoRA
Section titled “Training a LoRA”Training learns A and B from example images while the checkpoint stays frozen. The usual tools are outside ComfyUI: kohya-ss/sd-scripts, which wrote the ss_ metadata above, and the diffusers LoRA training guide. ComfyUI v0.36.0 also has experimental training nodes in nodes_train.py. TrainLoraNode takes the model, latents of the training images and their conditioning, and its inputs are the decisions any trainer asks for:
| Input | Default | What it decides |
|---|---|---|
rank |
8 | the size of A and B, and of the file |
steps, batch_size, grad_accumulation_steps |
16, 1, 1 | how long training runs, and how many images each update sees |
learning_rate, optimizer |
0.0005, AdamW | how far each update moves A and B |
loss_function |
MSE | how the predicted noise is compared with the real one |
training_dtype, lora_dtype |
bf16, bf16 | the precision of the frozen model and of the LoRA |
gradient_checkpointing, offloading |
on, off | memory against time |
algorithm |
LoRA | or LoHa, LoKr, OFT, other low-rank methods |
SaveLoRA writes the result to a .safetensors file, and LoraModelLoader applies it without saving. The node is marked experimental and has no tutorial in the documentation. This course doesn’t train a LoRA: how much of 16 GB training SDXL takes with these nodes is to verify.
Key takeaways
Section titled “Key takeaways”- A LoRA adds strength × (alpha / rank) × B·A to some of the checkpoint’s weights. Once added, it doesn’t slow the sampler.
- Read the header before trusting a LoRA: its rank and alpha are in the tensors, which are right, and in the metadata, which can be wrong.
LoraLoaderrecords patches. They are computed when the model is loaded, and the log says how many were attached.- A LoRA whose names don’t match the model does nothing, with only a warning in the log.
- Few-step LoRAs come with their own sampler, scheduler and CFG; take them from the card, and translate diffusers’ guidance 0 to ComfyUI’s CFG 1.
- Stacked LoRAs add up, whatever their order.
Your turn
Section titled “Your turn”Take a LoRA you downloaded and read its header before using it, with the course’s safetensors reader: its rank and alpha from the tensors, then from the metadata, and see whether they agree. Load it at three strengths on the base model it was trained for, then deliberately on another one, and find in the log the line that says how many patches were attached — that number is the difference between a LoRA that works and one that silently does nothing.
Exercises
Section titled “Exercises”- A LoRA’s header shows a layer with
lora_down.weightof shape 16 by 640,lora_up.weightof shape 640 by 16, andalpha8. Withstrength_model0.75, what multiplies B·A? - You load a LoRA made for Stable Diffusion 1.5 on SDXL base. The image is exactly the same as without it. What do you look for in the server log?
- Swap the two
LoraLoadernodes of07-lora-stack. Do you expect the same pixels?
Solution 1
The rank is 16, the first dimension of lora_down. The factor is 0.75 × 8 / 16 = 0.375.
Solution 2
lora key not loaded: lines, one per name in the file, and 0 patches attached when the SDXL model loads. SD 1.5’s layer names and shapes don’t match SDXL’s, so no patch is recorded, and the sampler runs the unchanged model. To verify: not run for this lesson.
Solution 3
The sum is the same in exact arithmetic, but floating-point addition isn’t associative: adding the two terms to W in the other order can change the last bits of some weights, and lesson 2 showed how small differences can grow over the steps. ComfyUI also rounds the result back to the model’s type with stochastic rounding, seeded by the layer’s name. Expect the same image to the eye, and not necessarily the same pixel hash. To verify: not rendered for this lesson.
Sources
Section titled “Sources”- E. Hu et al., LoRA: Low-Rank Adaptation of Large Language Models, 2021.
- S. Luo et al., LCM-LoRA: A Universal Stable-Diffusion Acceleration Module, 2023.
- S. Lin, A. Wang, X. Yang, SDXL-Lightning: Progressive Adversarial Diffusion Distillation, 2024.
- ComfyUI documentation: LoRA, multiple LoRAs,
LoraLoader,TrainLoraNode. - ComfyUI at v0.36.0:
nodes.py,comfy/sd.py,comfy/lora.py,comfy/weight_adapter/lora.py,comfy/model_patcher.py,comfy_extras/nodes_train.py. - Model cards: nerijs/pixel-art-xl, latent-consistency/lcm-lora-sdxl, ByteDance/SDXL-Lightning.