8. Recent models and their licenses, quantization and VRAM
Sections
Reading settings
No voice for this language in this browser.
More voices
Code and English terms
Off: the page’s voice reads everything, with no pause between two voices.
No voice for this language in this browser.
More voices
More voices: Microsoft Edge has natural online voices, and Windows (Settings › Time & language › Speech), macOS and Android install others.
Code: the workflows 08-z-image-turbo.api.json and 08-flux2-klein.api.json; the header reader in csharp/Safetensors.cs.
SDXL came out in July 2023, and the models of 2025 and 2026 are built differently. Their denoising network is a transformer instead of a UNet, trained with flow matching, which learns a straight path from noise to image. A language model reads the prompt instead of CLIP. And they are larger. This lesson runs two of them that are free for commercial use, reads their licenses and their files, and fits them in 16 GB.
Two models
Section titled “Two models”| Z-Image-Turbo | FLUX.2 klein 4B | |
|---|---|---|
| Maker | Tongyi-MAI, at Alibaba | Black Forest Labs |
| Denoising network | 6 billion parameters, a “Scalable Single-Stream DiT” | 4 billion parameters, a “rectified flow transformer” |
| Text encoder | Qwen3 4B | Qwen3 4B, the same file |
| Steps and CFG | 8 steps, CFG 1 | 4 steps, CFG 1, for the distilled model |
| License | Apache 2.0 | Apache 2.0 |
| Files for ComfyUI | Comfy-Org/z_image_turbo | Comfy-Org/flux2-klein-4B |
Both are distilled, like the LoRAs of lesson 7. Z-Image-Turbo “matches or exceeds leading competitors with only 8 NFEs”, 8 network evaluations, and its card says it “fits comfortably within 16G VRAM consumer devices”. The klein card says it “Runs on consumer GPUs (~13GB VRAM)”. The Qwen3 4B text encoder is the same 8.0 GB file in both Comfy-Org repositories, with the same SHA-256.
Their graphs
Section titled “Their graphs”The workflows copy ComfyUI’s blueprint Text to Image (Z-Image-Turbo), and the distilled branch of the template used by the FLUX.2 klein tutorial. There is no checkpoint file: each part has its own loader.
| Role | Z-Image-Turbo | FLUX.2 klein 4B |
|---|---|---|
| Denoising network | UNETLoader, then ModelSamplingAuraFlow with shift 3 |
UNETLoader |
| Text encoder | CLIPLoader, type lumina2 |
CLIPLoader, type flux2 |
| Negative prompt | ConditioningZeroOut of the positive one |
an empty CLIPTextEncode |
| Empty latent | EmptySD3LatentImage |
EmptyFlux2LatentImage |
| Sampling | KSampler, 8 steps, CFG 1, res_multistep, simple |
SamplerCustomAdvanced with RandomNoise, CFGGuider at CFG 1, KSamplerSelect euler, and Flux2Scheduler with 4 steps |
| VAE | ae.safetensors, saved here as z_image_ae.safetensors |
flux2-vae.safetensors |
CLIPLoader loads a language model here. In ComfyUI’s node names, “CLIP” now means any text encoder, and type tells ComfyUI how to use it. With CFG 1 the negative prompt is never evaluated (lesson 2), which is why both graphs give it an empty or zeroed conditioning. shift moves a flow model’s schedule towards the noisy end: time_snr_shift maps a time t to 3t / (1 + 2t), so the middle of the schedule, t = 0.5, becomes a noise level of 0.75.
Licenses
Section titled “Licenses”A model’s license is a dependency’s license. It says what you may do with the weights, and sometimes with the images, and it varies more than for code:
| Model | License | What it says |
|---|---|---|
| SDXL base 1.0 | CreativeML Open RAIL++-M | open use, with a list of forbidden uses that must be passed on with the model |
| Pixel Art XL, lesson 7 | CreativeML Open RAIL-M | the same idea, in its older version |
| Stable Diffusion 3.5 Large | Stability AI Community License | “Free for research, non-commercial, and commercial use for organizations or individuals with less than $1M in total annual revenue.” |
| FLUX.1 dev | FLUX.1 dev Non-Commercial License | the weights for non-commercial use, but “Generated outputs can be used for personal, scientific, and commercial purposes” |
| FLUX.1 schnell | Apache 2.0 | “can be used for personal, scientific, and commercial purposes” |
| Qwen-Image | Apache 2.0 | “Qwen-Image is licensed under Apache 2.0.” |
| Z-Image-Turbo | Apache 2.0 | |
| FLUX.2 klein 4B | Apache 2.0 | “Open weights available for commercial use” |
| FLUX.2 klein 9B | FLUX Non-Commercial License | from the 4B card: “Filters or manual review must be used with the FLUX.2 [klein] 9B models under the terms of the FLUX Non-Commercial License” |
Three traps show in this table. The license can change within a family: klein 4B and klein 9B don’t share one. It can depend on who you are, as with Stability AI’s revenue threshold. And a repackaged file, such as Comfy-Org’s, comes under the original model’s license, which you read on the original card. The course read each card when it downloaded the file, and its report lists every file with its license and SHA-256. This is not legal advice: read the license itself before shipping anything.
Read the license before publishing an output
Section titled “Read the license before publishing an output”A license can restrict where its outputs may be seen, not only what you do with the weights. This course found out the hard way, with image-to-3D models; the journal tells the story.
ComfyUI v0.36.0 runs Hunyuan3D 2 with core nodes. Its license, the Tencent Hunyuan 3D 2.0 Community License, starts with:
THIS LICENSE AGREEMENT DOES NOT APPLY IN THE EUROPEAN UNION, UNITED KINGDOM AND SOUTH KOREA AND IS EXPRESSLY LIMITED TO THE TERRITORY, AS DEFINED BELOW.
Clause 1.l defines the Territory: “the worldwide territory, excluding the territory of the European Union, United Kingdom and South Korea.” Clause 5.c goes further:
You must not use, reproduce, modify, distribute, or display the Tencent Hunyuan 3D 2.0 Works, Output or results of the Tencent Hunyuan 3D 2.0 Works outside the Territory. Any such use outside the Territory is unlicensed and unauthorized under this Agreement.
The Hunyuan3D 2.1 license has the same clauses. Three consequences for a public site:
- Where you are isn’t enough. Generating a mesh in a country inside the Territory is allowed. Putting it on a website isn’t a use in that country only: a public page is displayed in the European Union, the United Kingdom and South Korea too.
- A render is an output. “Output or results” covers more than the
.glbfile. A turntable image of the mesh, rendered in Blender, still displays the result. - A license is a file with a date. Read it at a pinned revision and keep its hash. The course reads the Hunyuan3D 2.0 license at commit
9cd649ba, SHA-256eca02cc10abaf520…. Some licenses change on their own: DINOv3’s, dated August 19, 2025, says in clause 8 that “Your continued use of the DINO Materials after any modification to this Agreement constitutes your agreement to such modification.”
The course compared three ways to get a 3D model of a small object for its pages:
| Hunyuan3D 2.0 or 2.1, in ComfyUI | TRELLIS.2 4B, in ComfyUI | Procedural modelling with bpy in Blender |
|
|---|---|---|---|
| License | Tencent Hunyuan 3D Community License: not in the EU, the UK or South Korea, outputs not displayed there, a request to Tencent above 1 million monthly active users | MIT, but its image encoder is DINOv3, under the DINOv3 License: acknowledge DINOv3 in a publication (1.b.ii), give a copy of the license with the weights (1.b.i), accept later changes by using them (8) | Blender is GPL, and its license page says “What you create with Blender is your sole property.” |
| Free RAM and VRAM on this machine | 19 GB of free RAM for 2.0 with SDXL; 9.4 GB of VRAM measured while sampling | about 23 GB of free RAM for the int8 model with SDXL; the upstream README asks for “at least 24GB” of VRAM, and 16 GB is to verify | no GPU needed |
| Quality observed | 890,140 and 1,017,760 triangles for two simple objects, 19,084 and 189,748 non-manifold edges, no UVs and no texture, an invented back, painted detail read as relief, and the image’s floor line turned into a slab | not tested | 3,370 triangles for the metronome and 5,950 for the gramophone, no non-manifold edge when the exported glTF is read back, named parts, separate materials and animations, for about 510 lines of modelling code and 120 more that check them on every commit; the detail stops where the code stops |
| Publishable on this site | no | yes, with DINOv3 acknowledged | yes |
Comfy-Org’s TRELLIS.2 repackage is tagged MIT and ships clip_vision/dino_v3_vit_l.safetensors without a copy of the DINOv3 License. The file’s own license still applies: a repackage doesn’t change it. This is not legal advice.
What is inside a quantized file
Section titled “What is inside a quantized file”Z-Image-Turbo’s 6 billion parameters take 12.3 GB in bf16, 2 bytes each, and the Qwen3 text encoder takes 8.0 GB more: 20.3 GB, for a 16 GB card. Comfy-Org publishes both in smaller formats. The course’s tool reads their headers:
> comfy safetensors-info z_image_turbo_bf16.safetensorsz_image_turbo_bf16.safetensors: header 48920 bytes, 453 tensors, 12.31 GB of tensor data  BF16       453 tensors,  12.31 GB
> comfy safetensors-info z_image_turbo_int8_convrot.safetensorsz_image_turbo_int8_convrot.safetensors: header 91000 bytes, 857 tensors, 6.20 GB of tensor data  I8         202 tensors,   6.14 GB  F32        453 tensors,   58.9 MB  U8         202 tensors, 14544 bytesquantized layers (.comfy_quant): 202  202 x {"format": "int8_tensorwise", "convrot": true, "convrot_groupsize": 256}
> comfy safetensors-info z_image_turbo_nvfp4.safetensorsz_image_turbo_nvfp4.safetensors: header 113080 bytes, 993 tensors, 4.51 GB of tensor data U8 180 tensors, 2.71 GB BF16 273 tensors, 1.46 GB F8_E4M3 180 tensors, 0.34 GB F32 360 tensors, 1440 bytesquantized layers (_quantization_metadata): 180 nvfp4- int8: 202 layers store one signed byte per weight, plus one
F32scale per layer: weight ≈ scale × byte. Each of these layers also has a tinyU8tensor namedcomfy_quant, which holds its format as JSON. Theconvrotflag and its group size of 256 select a variant whose kernels,quantize_int8_convrot_weightanddequantize_int8_convrot_weight, are in comfy-kitchen, ComfyUI’s quantization library. The kernel has since been read, in comfy-kitchen 0.2.34. The rotation is a regular Hadamard matrix: the Kronecker powers of a symmetric 4 × 4 block, divided by the square root of its size, which is why the group size has to be a power of 4 (tensor/int8_utils.py). Each group of 256 input channels is rotated by it — the weight once, offline, asW @ H.T, and the activations at every call, asx @ H, fused into the row-wise quantizer (backends/cuda/__init__.py). That matrix is symmetric and orthogonal, so it is its own inverse: the two rotations cancel and the layer computes the same product. What changes is what int8 has to hold.data/convrot.pyrebuilds the same matrix — identical to comfy-kitchen’s at group sizes 16, 64 and 256 — and quantizes a weight whose every row has one channel forty times the others: the row-wise round-trip error is 5.7 % without the rotation and 0.76 % with it, seven and a half times smaller. The rotation mixes the outlier into its whole group, so the row’s single scale no longer has to cover it alone. - nvfp4: 180 layers store 4 bits per weight, two to a byte, in
U8. NVIDIA’s NVFP4 format has “1 sign bit, 2 exponent bits, and 1 mantissa bit”: 16 possible values. Each block of 16 weights has its own 8-bitF8_E4M3scale, which is why 2.71 GB of weights come with 0.34 GB of scales, and each layer has twoF32scalars. The format isn’t stored in per-layer tensors here, but in the header’s_quantization_metadataentry. - The
BF16tensors of the nvfp4 file are not only small normalization weights. Reading their names shows that the 30 main blocks are quantized, but the four refiner blocks that first process the image and the text stay whole in bf16, 1.43 GB of the 1.46 GB.
The text encoder’s smaller files mix formats, which their names only half say:
> comfy safetensors-info qwen_3_4b_fp8_mixed.safetensorsqwen_3_4b_fp8_mixed.safetensors: header 87608 bytes, 788 tensors, 5.63 GB of tensor data  BF16       209 tensors,   3.27 GB  F8_E4M3    189 tensors,   2.33 GB  U8         201 tensors,   31.5 MB  F32        189 tensors, 756 bytesquantized layers (.comfy_quant): 189  177 x {"format": "float8_e4m3fn"}  12 x {"format": "nvfp4"}
> comfy safetensors-info qwen_3_4b_fp4_mixed.safetensorsqwen_3_4b_fp4_mixed.safetensors: header 121208 bytes, 1081 tensors, 3.48 GB of tensor data  F8_E4M3    247 tensors,   1.24 GB  U8         436 tensors,   1.21 GB  BF16       151 tensors,   1.03 GB  F32        247 tensors, 988 bytesquantized layers (.comfy_quant): 247  189 x {"format": "nvfp4"}  58 x {"format": "float8_e4m3fn"}
The “fp8” file has 12 nvfp4 layers, and the “fp4” file keeps 58 layers in fp8. float8_e4m3fn is one byte per weight with 4 exponent bits and 3 mantissa bits, and a scale per layer. On a GPU without fp4 kernels, the “fp8” file is therefore not entirely native either.
Three ways of writing the same numbers go through one loader. convert_old_quants turns the header entry into comfy_quant tensors when the file loads, and pick_operations then gives the model ComfyUI’s mixed-precision layers.
Native or emulated
Section titled “Native or emulated”A format is only fast on a GPU that has kernels for it. get_disabled_quant_formats asks model_management.py about the device:
| Format | Native on | Elsewhere |
|---|---|---|
float8_e4m3fn, float8_e5m2 |
NVIDIA with compute capability 8.9 or more: RTX 40 series and later | emulated |
nvfp4 |
NVIDIA with compute capability 10 or more: RTX 50 series | emulated |
int8_tensorwise |
any device except Apple’s MPS, Intel XPU and DirectML | emulated |
Emulated doesn’t mean refused. The layer is marked _full_precision_mm, and at each forward pass its weight is dequantized to the compute type, then multiplied as usual:
if self._full_precision_mm and isinstance(weight, QuantizedTensor): weight = weight.dequantize()return self._forward(input, weight, bias)The file stays small, on disk and in memory, and the computation costs more than bf16’s. The server logs its choice when a model loads. On the author’s RTX 5080, compute capability 12.0, with PyTorch built for CUDA 13.0, every format was native:
Using mixed precision operationsNative ops: asym_w4a8_int8, float8_e5m2, convrot_w4a4, float8_e4m3fn, mxfp8, nvfp4, int8_tensorwiseTo verify: the emulated path on an older GPU; the course’s machine has none.
Fitting in 16 GB
Section titled “Fitting in 16 GB”Dynamic VRAM
Section titled “Dynamic VRAM”The weights of bf16 Z-Image-Turbo and its text encoder don’t fit in 16 GB, and the workflow ran anyway. In v0.36.0 on NVIDIA, ComfyUI manages memory with dynamic VRAM, enabled by default: main.py replaces the model patcher with ModelPatcherDynamic when PyTorch is 2.8 or later. Each model is staged: its weights stay in system memory, and go to the GPU as the computation needs them, within the memory that is free. The log gives each model’s staged size:
Model ZImageTEModel_ prepared for dynamic VRAM loading. 7671MB Staged. 0 patches attached. Force pre-loaded 145 weights: 383 KB.Model Lumina2 prepared for dynamic VRAM loading. 11738MB Staged. 0 patches attached. Force pre-loaded 205 weights: 1045 KB.This changes what nvidia-smi tells you. The GPU’s peak memory was between 12.5 and 15.3 GB for every configuration below, with 2.4 to 2.8 GB already used by other programs: ComfyUI fills what is free, whatever the model’s size. The staged sizes and the speed show the difference.
Measured
Section titled “Measured”One server per configuration, three renders each: seed 42 on a fresh server, then seeds 43 and 44 with the models loaded. The prompt is lesson 1’s, at 1024 by 1024 pixels. Times are the server’s “Prompt executed” lines, and the speed is the sampler’s steps per second on the warm renders.
| Denoising network | Text encoder | Staged, network + encoder | First render | Warm renders | Steps per second |
|---|---|---|---|---|---|
| Z-Image-Turbo bf16 | Qwen3 bf16 | 11,738 + 7,671 MB | 63.93 s | 8.72 s, 5.93 s | 1.5 |
| Z-Image-Turbo int8 convrot | Qwen3 fp8 mixed | 5,888 + 5,370 MB | 37.42 s | 3.03 s, 3.05 s | 3.1 |
| Z-Image-Turbo nvfp4 | Qwen3 fp4 mixed | 4,299 + 3,317 MB | 28.06 s | 2.68 s, 2.79 s | 3.7 |
| Z-Image-Turbo nvfp4 | Qwen3 bf16 | 4,299 + 7,671 MB | 32.32 s | 2.41 s, 2.50 s | 4.1 |
| FLUX.2 klein 4B bf16, 4 steps | Qwen3 bf16 | 7,392 + 7,671 MB | 32.26 s | 2.00 s, 2.39 s | 3.5 |
The first render includes reading the files from an external SSD, and is mostly loading. The warm renders show the formats. bf16 ran at half the speed of int8: 11.7 GB of network, plus the working memory of a 1024 by 1024 image, didn’t fit next to the other programs, so some weights moved to the GPU at each step. int8 and nvfp4 fit, and nvfp4’s kernels were the fastest. The nvfp4 network also ran faster with the bf16 text encoder than with the fp4 one, 4.1 steps per second against 3.7. To verify: the course has no explanation for that, since the text encoder isn’t used during sampling.
A mode that loads whole models couldn’t be measured on this machine. With --disable-dynamic-vram, ComfyUI estimates the memory it needs and loads each model entirely. The first render took 78.87 seconds, and its pixels were identical to those of the dynamic VRAM render with the same seed. During the second render the machine, with 64 GB of RAM shared with other work, ran short of memory, and the run was stopped. That is a result in itself: dynamic VRAM is what lets a 20 GB model run next to other programs.
What quantization changed
Section titled “What quantization changed”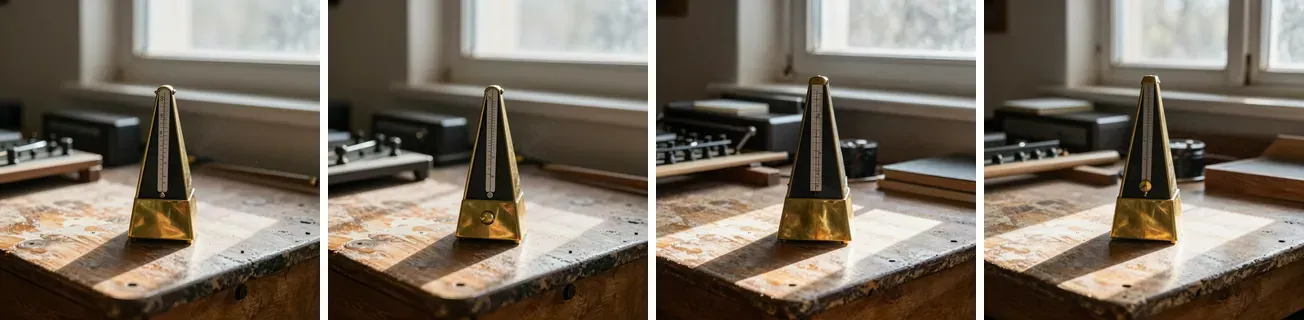
Rendered by ComfyUI v0.36.0: Z-Image-Turbo, seed 42, 8 steps, CFG 1, res_multistep, simple, shift 3, prompt “a brass metronome on an old wooden workbench, morning light through a window, dust in the air, photograph”, workflow 08-z-image-turbo.api.json. From left to right: bf16 network with the bf16 text encoder; int8 convrot with fp8 mixed; nvfp4 with fp4 mixed; nvfp4 with bf16.
Compared with the bf16 render of the same seed, pixel by pixel:
| Configuration | Seed 42 | Seed 43 | Seed 44 |
|---|---|---|---|
| int8 + fp8 mixed | mean 3.96, 13.13 % of the pixels by more than 8 | mean 3.27, 9.49 % | mean 4.78, 15.33 % |
| nvfp4 + fp4 mixed | mean 23.80, 71.98 % | mean 24.31, 66.18 % | mean 30.50, 74.48 % |
| nvfp4 + bf16 | mean 27.10, 71.35 % | mean 28.74, 72.73 % | mean 18.54, 62.58 % |
int8 gave the same picture, with small differences in texture. nvfp4 gave another picture of the same scene: the objects moved, and about three quarters of the pixels changed. The text encoder’s precision mattered too: nvfp4 with the fp4 encoder and with the bf16 encoder differed by a mean of 20 to 23 levels. None of these images is wrong, and different doesn’t mean worse. A quantized model is another model, close to the original, and a seed chosen with one doesn’t carry over to the other.
FLUX.2 klein
Section titled “FLUX.2 klein”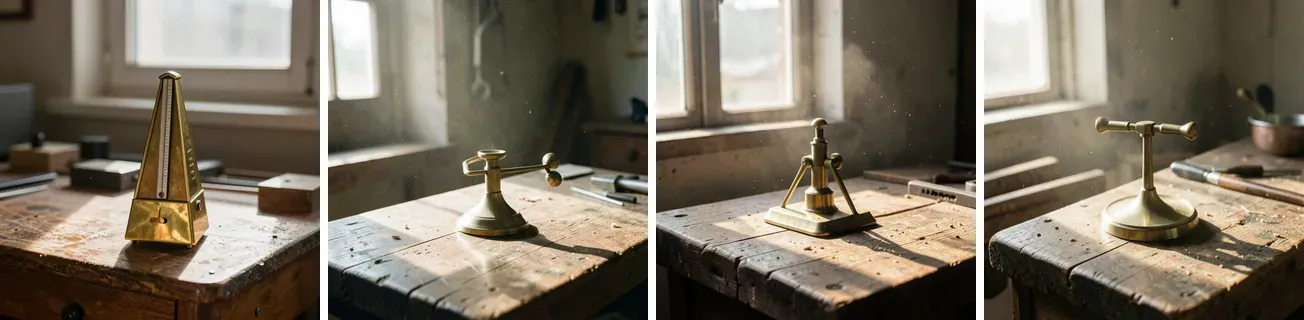
Rendered by ComfyUI v0.36.0. First: Z-Image-Turbo bf16, seed 43, settings as above. Then: FLUX.2 klein 4B distilled, bf16, with the Qwen3 4B text encoder, seeds 42, 43 and 44, 4 steps, CFG 1, euler, Flux2Scheduler, same prompt, workflow 08-flux2-klein.api.json.
With the same prompt, Z-Image-Turbo drew a metronome with every seed, and klein 4B drew a brass stand three times, in a scene that matches the rest of the prompt well. Lesson 1’s SDXL drew something like an hourglass. Recognizing an object from its name is where the models differed most on this prompt, but three seeds are not a benchmark.
GGUF and --lowvram
Section titled “GGUF and --lowvram”Guides written for older ComfyUI versions often recommend GGUF files, the format of llama.cpp, and the --lowvram flag. In v0.36.0 neither is the default path. ComfyUI’s core has no GGUF loader: ComfyUI-GGUF is a custom node, and its README says “Simply use the GGUF Unet loader found under the bootleg category.” ComfyUI’s own startup warning, printed with --disable-dynamic-vram, argues against it: “If you use gguf we recommend keeping dynamic vram enabled and using native ComfyUI model formats instead. ComfyUI native formats like fp8, int8 and w4a8 will be faster even if they are larger than your memory.” And the help of --lowvram says: “Doesn’t do anything if dynamic vram is enabled.”
Key takeaways
Section titled “Key takeaways”- Recent models split into a denoising transformer, a language-model text encoder and a VAE, each with its own loader, and are often distilled to a few steps with CFG 1.
- Read the license on the original model card, for the exact model and size: klein 4B is Apache 2.0, klein 9B is not.
- A quantized file’s header says what it holds: int8 and nvfp4 layers with their scales, layers left in bf16, and formats mixed in one file whatever its name says.
- A format runs natively only on GPUs that have its kernels. Elsewhere ComfyUI dequantizes at each step: the file stays small, and the speed is lost.
- Dynamic VRAM, on by default on NVIDIA, runs models larger than the GPU.
nvidia-smithen shows what is free, not what the model needs, and--lowvramdoes nothing. - int8 kept the image close to bf16 here; nvfp4 made another image of the same scene, at twice the speed of bf16.
Your turn
Section titled “Your turn”Pick a model you actually plan to use and do the two readings this lesson does. Read its header and count the bytes per format: how much is int8 or fp4, how much stayed in bf16, and how far the file is from the size its name suggests. Then read its license on the original model card, for the exact size you downloaded — not for the family — and decide before you generate whether what comes out may be published where you intend to publish it.
Exercises
Section titled “Exercises”- A 4 billion parameter network is stored in bf16, then in int8 with one scale per layer, then in nvfp4 with every weight quantized. Estimate each file’s size.
- You run
z_image_turbo_nvfp4.safetensorson an RTX 4090, compute capability 8.9. What does the “Native ops” log line list, and what happens to the nvfp4 layers? - A client wants product images for an online shop, rendered by FLUX.2 klein. Which klein model can you use, and what do you check first?
Solution 1
bf16 is 2 bytes per weight: about 8 GB. int8 is 1 byte: about 4 GB, plus a few scalars. nvfp4 is half a byte per weight, plus one 1-byte scale per block of 16 weights, 1/16 of a byte per weight: about 4 × 0.5625 = 2.25 GB. Real files are larger, because layers such as normalizations, embeddings and, in Z-Image-Turbo’s case, the refiner blocks stay in bf16: klein 4B’s bf16 file is 7.75 GB, and Z-Image-Turbo’s nvfp4 file keeps 1.46 GB in bf16.
Solution 2
supports_nvfp4_compute requires compute capability 10 or more, so nvfp4 moves to the emulated list: the line lists float8_e4m3fn, float8_e5m2, int8_tensorwise and the other formats as native, and nvfp4 after “emulated ops”. The model loads, and each nvfp4 layer is dequantized to bf16 at every forward pass: the memory saving remains, and the speed of the fp4 kernels is lost. To verify: the course’s machine has no RTX 40 series GPU; this follows from the code.
Solution 3
klein 4B, under Apache 2.0, allows commercial use; klein 9B is under the FLUX Non-Commercial License. Check the license on Black Forest Labs’ card for the exact file you download, including a repackaged one, and keep a record of it with the file’s hash. Then check what the license says about outputs, and the shop’s own rules for generated images. This isn’t legal advice.
Sources
Section titled “Sources”- Z-Image Team, Z-Image: An Efficient Image Generation Foundation Model with Single-Stream Diffusion Transformer, 2025.
- NVIDIA, Introducing NVFP4 for Efficient and Accurate Low-Precision Inference, 2025.
- ComfyUI documentation: Z-Image-Turbo, FLUX.2 klein.
- ComfyUI at v0.36.0:
QUANTIZATION.md,comfy/ops.py,comfy/quant_ops.py,comfy/model_management.py,comfy/utils.py,comfy/cli_args.py,main.py. - Model cards: Tongyi-MAI/Z-Image-Turbo, Comfy-Org/z_image_turbo, black-forest-labs/FLUX.2-klein-4B, Comfy-Org/flux2-klein-4B, and the license comparison’s stabilityai/stable-diffusion-3.5-large, black-forest-labs/FLUX.1-dev, black-forest-labs/FLUX.1-schnell, Qwen/Qwen-Image.
- city96/ComfyUI-GGUF.