2. Diffusion, and what makes an image reproducible
Sections
Reading settings
No voice for this language in this browser.
More voices
Code and English terms
Off: the page’s voice reads everything, with no pause between two voices.
No voice for this language in this browser.
More voices
More voices: Microsoft Edge has natural online voices, and Windows (Settings › Time & language › Speech), macOS and Android install others.
Code: the workflow is the one from lesson 1, workflows/01-txt2img.api.json, changed one input at a time. The comparisons use the compare command of the course’s C# tool, in csharp/Png.cs.
Diffusion in one page
Section titled “Diffusion in one page”A diffusion model is trained on a simple task. Take an image from the training set, add a random amount of Gaussian noise, and ask the network to predict the noise that was added. Repeat this over a very large number of images and noise levels, and the network learns what images look like at every level of blur and grain. The method comes from Denoising Diffusion Probabilistic Models (Ho, Jain and Abbeel, 2020).
Generating runs the task backwards. Start from pure noise, ask the network which part of it is noise, remove some of that, and repeat. Each repetition is a step. After enough steps, what is left looks like an image from the training distribution. A text prompt steers the prediction at every step, so the image drifts towards what the text describes.
Three refinements make this practical, and each one is a node in the lesson 1 graph.
Latent space: the VAE. Denoising 1024 × 1024 RGB pixels is expensive. Latent diffusion (Rombach et al., 2021) first trains an autoencoder, the VAE, that compresses an image to a much smaller latent tensor and back, then runs diffusion on latents. For SDXL, a 1024 × 1024 image becomes 4 channels of 128 × 128: 65,536 values instead of 3,145,728, 48 times fewer. That is why EmptyLatentImage creates torch.zeros([batch_size, 4, height // 8, width // 8]) (nodes.py, line 1265), and why VAEDecode comes last. The compression is lossy: the model card says “The autoencoding part of the model is lossy.”
Text encoders: CLIP. The prompt reaches the network as vectors, not words. CLIP (Radford et al., 2021) was trained to place an image and its caption close together in the same vector space, so its text half turns a prompt into vectors that mean something visual. SDXL uses two text encoders, “OpenCLIP ViT-bigG in combination with CLIP ViT-L”, and concatenates their outputs (SDXL paper). In ComfyUI both hide behind one CLIP output and one CLIPTextEncode node.
The denoising network. SDXL’s is a UNet, a convolutional network with attention layers where the text vectors come in. Its paper describes “a three times larger UNet backbone” than earlier Stable Diffusion versions. In ComfyUI it is the MODEL output, and KSampler calls it once or twice per step.
| In the paper | In the graph | Size loaded on this machine |
|---|---|---|
| Text encoders, CLIP ViT-L and OpenCLIP ViT-bigG | CLIP → CLIPTextEncode |
1,560 MB |
| Denoising UNet | MODEL → KSampler |
4,896 MB |
| Autoencoder | VAE → VAEDecode |
159 MB |
| The initial noise | made inside KSampler, from the seed |
— |
Where the noise comes from
Section titled “Where the noise comes from”The EmptyLatentImage node doesn’t make noise; its latent is all zeros. KSampler makes the noise, in comfy/sample.py:
def prepare_noise_inner(latent_image, generator, noise_inds=None):    if noise_inds is None:        return torch.randn(latent_image.size(), dtype=torch.float32, layout=latent_image.layout, generator=generator, device="cpu").to(dtype=latent_image.dtype)
def prepare_noise(latent_image, seed, noise_inds=None):    generator = torch.manual_seed(seed)
The seed initializes PyTorch’s random number generator, and the noise is drawn on the CPU, then moved to the GPU. So the starting noise for a given seed and latent size doesn’t depend on the graphics card. It is like new Random(42) in C# or Java: the same seed gives the same sequence. What happens to that noise afterwards runs on the GPU, and that is where reproducibility gets harder, as the second half of this lesson shows. ComfyUI’s text-to-image tutorial says that EmptyLatentImage “constructs a pure noise latent space”; the code says otherwise.
The sampler’s inputs, one at a time
Section titled “The sampler’s inputs, one at a time”All the images below were rendered by ComfyUI v0.36.0 from the lesson 1 workflow with one input changed. Every image: Stable Diffusion XL base 1.0, 1024 × 1024, positive prompt “a brass metronome on an old wooden workbench, morning light through a window, dust in the air, photograph”, negative prompt “blurry, text, watermark”, workflow 01-txt2img.api.json, reduced for this page. Unless the caption says otherwise: seed 42, 25 steps, CFG 7, euler sampler, normal scheduler.
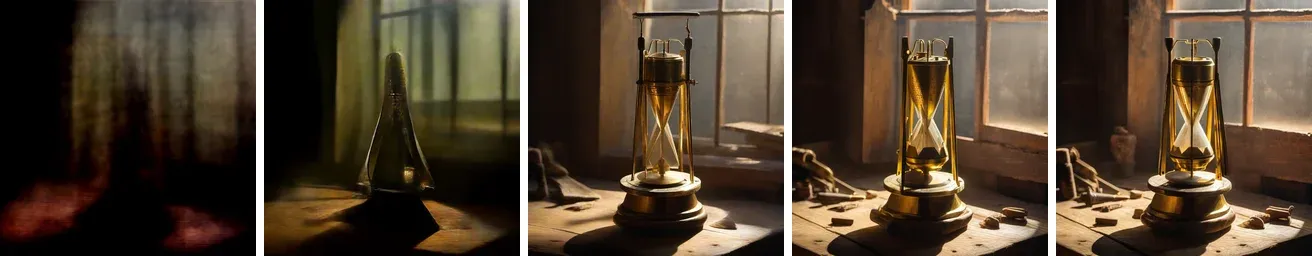
Seed 42; 1, 4, 10, 25 and 50 steps.
With one step, the sampler removes all the noise it predicts in one jump, and gets a blur. The scene appears between 4 and 10 steps. From 25 to 50 the composition stays but the details change: the comparison tool finds 99.37 % of the pixels different, 40.87 % by more than 8 levels out of 255. More steps is not a refinement of the same image, it is a different path through the same model. The run time, with the prompts already encoded, grows with the steps: 0.83 s for 1 step, 2.15 s for 10, 4.6 s for 25, 8.56 s for 50.
CFG, classifier-free guidance
Section titled “CFG, classifier-free guidance”At each step, the sampler runs the network twice: once with the positive prompt, once with the negative one. It then moves away from the negative prediction and towards the positive one, in comfy/samplers.py:
cfg_result = uncond_pred + (cond_pred - uncond_pred) * cond_scalecond_scale is the cfg input. With 1, the result is the positive prediction alone. With 7, the difference between the two predictions is multiplied by seven. The method is from Classifier-Free Diffusion Guidance (Ho and Salimans, 2022).
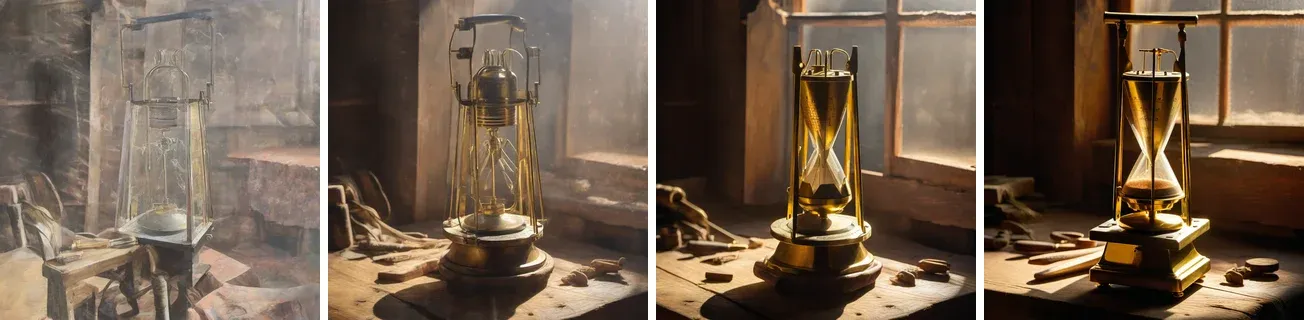
Seed 42; CFG 1, 3, 7 and 12.
Here, low CFG followed the prompt loosely and gave pale, hazy images, and higher CFG gave more contrast and saturation. CFG 1 was also faster: 3.29 s instead of about 4.6 s. The sampler skips the negative prediction when the scale is 1 (samplers.py, lines 609 to 613), since it wouldn’t change the result, so each step runs the network once instead of twice.
Sampler and scheduler
Section titled “Sampler and scheduler”The scheduler decides the noise level at each step: how fast the noise goes down, from the highest level to zero. The sampler is the numerical method that goes from one level to the next, much like choosing between Euler and Runge-Kutta to solve a differential equation. Karras et al. (2022) framed samplers this way, and gave their name to the karras scheduler, which spends more steps at low noise levels. dpmpp_2m is a second-order solver from DPM-Solver++ (Lu et al., 2022). ComfyUI 0.36.0 offers 45 samplers and 9 schedulers.
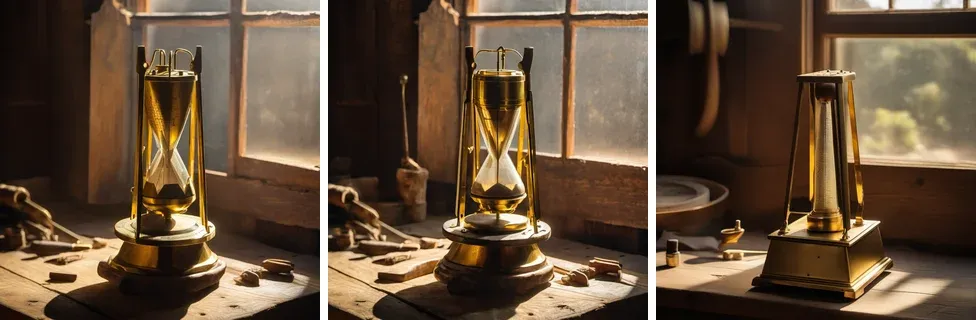
Seed 42; euler with normal, dpmpp_2m with karras, euler_ancestral with normal.
euler and dpmpp_2m kept the composition: the tool measured a mean difference of 14.2 levels, against 39.2 for euler_ancestral. euler_ancestral is an ancestral sampler: at each step, it removes a bit more noise than predicted and adds fresh random noise back, so it can wander further from the path the other two follow. The fresh noise is seeded too, so a second run of the same graph gave the same pixels. But look at where that noise comes from, in comfy/k_diffusion/sampling.py:
def default_noise_sampler(x, seed=None):    if seed is not None:        if x.device == torch.device("cpu"):            seed += 1
        generator = torch.Generator(device=x.device)        generator.manual_seed(seed)
Unlike the initial noise, it is drawn on x.device, the GPU when there is one. The random number generators of the CPU and of CUDA don’t produce the same numbers for the same seed, and the code even offsets the seed on the CPU. An ancestral sampler’s image for a given seed is therefore expected to depend on the device; this course didn’t render SDXL on the CPU to measure it, so that is to verify.
Seed and batch
Section titled “Seed and batch”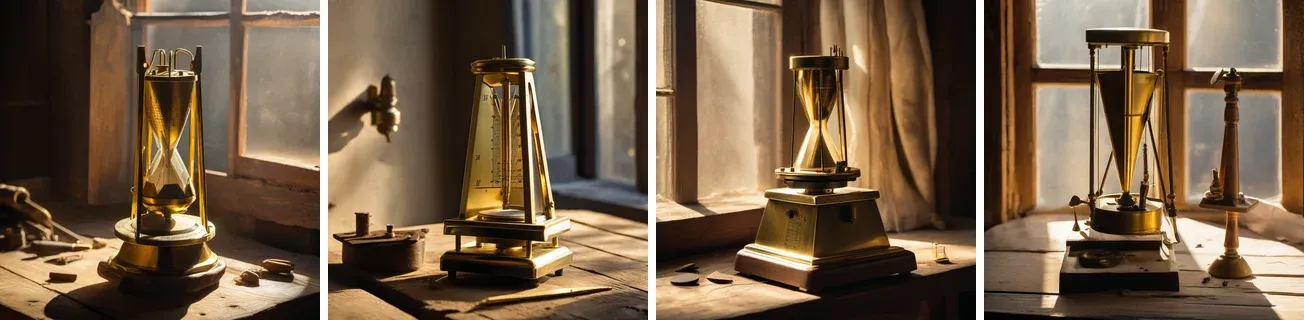
Seeds 42, 43 and 7; then the second image of a batch of two with seed 42 (batch_size 2).
Every seed is a different image; the prompt only sets what they have in common. A batch of two with seed 42 doesn’t give the images of seeds 42 and 43: prepare_noise draws one noise tensor for the whole batch from one generator, so the second image gets the numbers that follow the first image’s in the sequence. The first image of the batch looked like the single seed-42 image, but wasn’t identical to it; the next section explains why.
Reproducibility, measured
Section titled “Reproducibility, measured”The KSampler documentation says that the same seed “generates identical images”. PyTorch’s reproducibility notes are more careful: “Completely reproducible results are not guaranteed across PyTorch releases, individual commits, or different platforms. Furthermore, results may not be reproducible between CPU and GPU executions, even when using identical seeds.”
To find out on one machine, every render in this lesson was hashed: the SHA-256 of its decoded pixels, first 16 hexadecimal digits, printed by the C# tool. The pixels, not the file: two PNGs of the same pixels differ as soon as their metadata differs, and lesson 3 shows that even the compressed bytes depend on the zlib library.
| Same workflow, seed 42 | Pixel hash |
|---|---|
| First run after starting the server | 698e7867e7fc04fb |
| First run after a restart, twice | 698e7867e7fc04fb |
First run after starting with --deterministic |
698e7867e7fc04fb |
| Run again after changing the negative prompt and changing it back | 5374ac40a393cf78 |
The same, after --deterministic |
5374ac40a393cf78 |
First run after starting with --disable-dynamic-vram |
5374ac40a393cf78 |
| Queued from the browser, after API runs | 5374ac40a393cf78 |
| The first image of a batch of two | 3a5c00b46e6f4956 |
So the same graph, with the same seed, the same model and the same server, gave two different images, each one reproducibly. The difference is not the seed:
> comfy compare default-cold_00001_.png default-warm2_00001_.pngidentical pixels: nolargest difference: 182 of 255, mean 0.922pixels that differ: 68.02 %, by more than 8: 2.63 %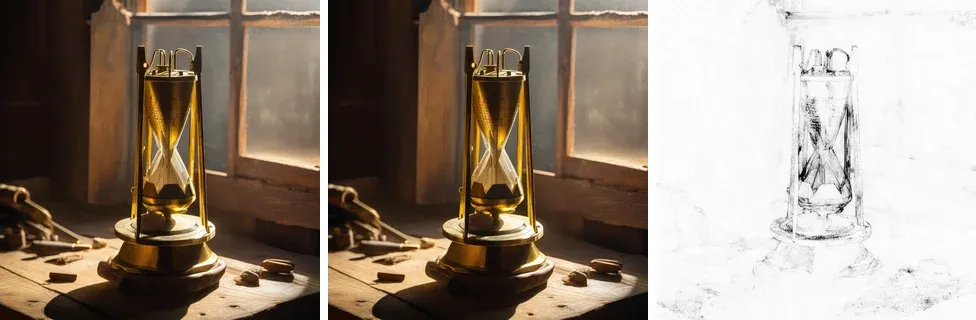
Left: first run after starting the server. Middle: the same graph run again after the negative prompt was re-encoded. Right: where they differ, eight times amplified, dark where the difference is large.
The two images differ along edges and fine details, which is what small numerical differences in the denoising produce. What decides between them is the order in which the networks were loaded:
- On a fresh server, the text encoders run before the UNet is on the GPU, and give
698e…. - When the negative prompt is encoded again later, the UNet is already loaded, and the result is
5374…. - With
--disable-dynamic-vram, which turns off the loading mode the log reports asDynamicVRAM support detected and enabled, the first run already gives5374…. --deterministic, which asks PyTorch for deterministic algorithms, changed nothing: its help text warns that it “might not make images deterministic in all cases”.
This course hasn’t traced which operation differs between the two loading states; that is to verify, and noted in the course’s journal.
The batch is a third case. Its first image has the same starting noise as the single image, but the denoising runs on a tensor of two images at once, and the GPU kernels for a batch of two don’t round exactly like those for one: mean difference 0.739, 1.49 % of the pixels by more than 8 levels.
What did reproduce exactly:
- the same graph after restarting the server, three times;
- seed 43, run by the Java client of lesson 4 on a later server, against the same seed rendered earlier: identical pixels;
euler_ancestral, run twice in a row.
What reproducibility means in practice:
- Keep the prompt JSON with the image. ComfyUI already writes it into the PNG.
- Record what isn’t in the JSON: the model file’s SHA-256, the ComfyUI commit, the PyTorch and driver versions, the GPU, and the server’s flags.
- Compare pixels with a tolerance, not files with a hash, when a test checks a render. A tolerance is not a perceptual hash; the course hasn’t checked whether a perceptual hash would be stable across these cases.
- Expect a different image on another GPU, another PyTorch or another OS. None of that was measured here, so it is to verify.
Key takeaways
Section titled “Key takeaways”- A checkpoint is three networks: text encoders that turn the prompt into vectors, a denoising UNet that runs in a 48 times smaller latent space, and a VAE that converts between latents and pixels.
KSamplerdraws the starting noise from the seed on the CPU, then denoises on the GPU forstepssteps, calling the UNet twice per step unless CFG is 1.- Steps, CFG, sampler, scheduler and seed each change the image, not just its quality; ancestral samplers add seeded noise at every step, drawn on the GPU.
- On one machine, the same graph and seed gave identical pixels across restarts, but a different image when the text encoders ran after the UNet was loaded, and in a batch. Record the whole environment, and compare pixels with a tolerance.
Your turn
Section titled “Your turn”Take a prompt of your own and measure, rather than look. Render it once, restart the server, render it again with the same seed, and compare the two PNG files with compare from the course’s C# tool: the numbers, not your eyes, say whether anything moved. Then render the same seed inside a batch of four and compare the batch’s first image with the single one. Write down what your machine does, the way this lesson does — it is your machine’s answer, not this one’s, that you will rely on later.
Exercises
Section titled “Exercises”- A 1344 × 768 image has the same number of pixels as 1024 × 1024, give or take. What is the size of its latent, and is the ratio of values the same?
- Render seed 42 twice with CFG 1 and compare the two files with
comfy compare. Then render with CFG 1 and CFG 1.01: which is faster, and why? prepare_noisetakes anoise_indsargument, filled from the latent’sbatch_index. Readprepare_noise_inner: what does it do with the generator for indexes that aren’t in the batch, and what problem does that solve?
Solution 1
The latent is 4 channels of 168 × 96, because EmptyLatentImage divides each side by 8: 64,512 values. The image has 3 × 1344 × 768 = 3,096,576 values. The ratio is 48, as for 1024 × 1024: 3 channels of pixels against 4 channels at one sixty-fourth of the area, 64 × 3 / 4 = 48, whatever the size.
Solution 2
Queue the second CFG 1 render unchanged and nothing runs: the server reuses its cached result and writes no new file, so change the filename_prefix to get a second file. Only SaveImage runs then, from the cached image, and compare says identical pixels: yes by construction; to compare two real renders, restart the server between them. CFG 1.01 is slower, like CFG 7: math.isclose(cond_scale, 1.0) is false for 1.01, so the sampler runs the network for the negative prompt at every step again. The image changes very little, since the difference between the predictions is multiplied by 1.01 instead of 1.
Solution 3
unique_inds, inverse = np.unique(noise_inds, return_inverse=True)noises = []for i in range(unique_inds[-1]+1): noise = torch.randn([1] + list(latent_image.size())[1:], dtype=torch.float32, layout=latent_image.layout, generator=generator, device="cpu").to(dtype=latent_image.dtype) if i in unique_inds: noises.append(noise)It draws the noise for every index from 0 to the largest one, and keeps only the indexes of the batch. Drawing and discarding moves the generator forward, so the image at index 3 of a batch, counting from 0, always gets the noise it would have had as the fourth image of the full batch. That makes it possible to render one image of a batch again on its own, with the same noise.
Sources
Section titled “Sources”- J. Ho, A. Jain, P. Abbeel, Denoising Diffusion Probabilistic Models, 2020.
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser, B. Ommer, High-Resolution Image Synthesis with Latent Diffusion Models, 2021.
- A. Radford et al., Learning Transferable Visual Models From Natural Language Supervision, 2021.
- J. Ho, T. Salimans, Classifier-Free Diffusion Guidance, 2022.
- T. Karras, M. Aittala, T. Aila, S. Laine, Elucidating the Design Space of Diffusion-Based Generative Models, 2022.
- C. Lu et al., DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models, 2022.
- D. Podell et al., SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis, 2023.
- ComfyUI at v0.36.0:
comfy/sample.py,comfy/samplers.py,comfy/k_diffusion/sampling.py; KSampler documentation. - PyTorch, Reproducibility.