1. The node graph, installing, and a first image
Sections
Reading settings
No voice for this language in this browser.
More voices
Code and English terms
Off: the page’s voice reads everything, with no pause between two voices.
No voice for this language in this browser.
More voices
More voices: Microsoft Edge has natural online voices, and Windows (Settings › Time & language › Speech), macOS and Android install others.
Code: the workflow of this lesson, workflows/01-txt2img.api.json, and the course’s C# tool, whose png-info command is in csharp/Png.cs.
What ComfyUI is, for a C# or Java developer
Section titled “What ComfyUI is, for a C# or Java developer”ComfyUI generates images, and more recently video, audio and 3D models, with diffusion models. You don’t write a script: you build a graph of nodes in the browser, and a Python server runs it. Each node does one thing, such as loading a model file, encoding a prompt, or sampling, and passes its results to the next nodes through typed connections.
Two pieces work together:
- The server is a Python program,
main.py, built on PyTorch and aiohttp. It holds the node definitions, a queue of prompts, and a cache of node results, and it serves an HTTP and WebSocket API on port 8188. - The frontend is a web application, published as the Python package
comfyui-frontend-packageand served by the same server. It draws the graph, and when you press Run it converts the graph into a prompt and posts it to the API. Lesson 3 looks at both JSON formats, and lesson 4 calls the API from C# and Java.
If you have used TPL Dataflow or a build system, the model is familiar. Nodes are blocks with typed inputs and outputs. The server only runs the nodes that an output node needs, in dependency order. And like an incremental build, it skips a node whose inputs haven’t changed since the last run and reuses its cached result.
A node is a Python class. Here is EmptyImage, one of the simplest, in nodes.py at v0.36.0:
class EmptyImage: @classmethod def INPUT_TYPES(s): return {"required": { "width": ("INT", {"default": 512, "min": 1, "max": MAX_RESOLUTION, "step": 1}), "height": ("INT", {"default": 512, "min": 1, "max": MAX_RESOLUTION, "step": 1}), "batch_size": ("INT", {"default": 1, "min": 1, "max": 4096}), "color": ("INT", {"default": 0, "min": 0, "max": 0xFFFFFF, "step": 1, "display": "color"}), }} RETURN_TYPES = ("IMAGE",) FUNCTION = "generate"INPUT_TYPES declares the inputs and their constraints, RETURN_TYPES the outputs, and FUNCTION names the method the server calls. In C# terms, it is a class whose attributes describe its parameters, discovered by reflection. The server publishes these declarations as JSON at /object_info, and the frontend builds its widgets from them. You don’t need to write Python in this course until lesson 11, which covers custom nodes.
The versions
Section titled “The versions”| Piece | Version |
|---|---|
| ComfyUI | v0.36.0, commit ee71d5c, released on 15 September 2026 |
| Frontend | comfyui-frontend-package 1.52.7, the version requirements.txt pins |
| Python and PyTorch | Python 3.13.14 and PyTorch 2.13.0 for CUDA 13.0, as shipped in the Windows portable build |
| Model | Stable Diffusion XL base 1.0, revision 4621659 |
| Machine | Windows 11, an NVIDIA GeForce RTX 5080 with 16 GB, driver 610.88, 64 GB of RAM |
ComfyUI publishes a release about every week, and its README warns that commits between release tags “may be very unstable and break many custom nodes”. Every link to ComfyUI’s code in this course points at the v0.36.0 commit, so the line numbers stay right.
Installing ComfyUI
Section titled “Installing ComfyUI”The portable build bundles its own Python, PyTorch and ComfyUI in one archive. For a recent NVIDIA card, download ComfyUI_windows_portable_nvidia.7z from the v0.36.0 release: 1,917,442,353 bytes, about 1.8 GB. Extract it with 7-Zip or with Explorer, then start it:
cd ComfyUI_windows_portable.\run_nvidia_gpu.batThe batch file runs .\python_embeded\python.exe -s ComfyUI\main.py --windows-standalone-build. The release also has builds for older NVIDIA cards (CUDA 12.6), for AMD and for Intel GPUs; this course only ran the NVIDIA one.
There is no official installer or container image, so you install ComfyUI as a Python application, in a virtual environment. The manual install page uses conda; a venv works the same way:
git clone --depth 1 --branch v0.36.0 https://github.com/Comfy-Org/ComfyUI.gitcd ComfyUIpython3.13 -m venv .venvsource .venv/bin/activate# NVIDIA GPU (CUDA 13.0)pip install torch torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/cu130# or, without a GPU:# pip install torch==2.13.0 torchvision==0.28.0 torchaudio --index-url https://download.pytorch.org/whl/cpupip install -r requirements.txtpython main.pyThe CPU variant is what the course’s CI runs on Ubuntu. The CUDA variant is to verify: the course’s GPU machine runs Windows.
On Apple Silicon, PyTorch runs on the GPU through MPS, Apple’s Metal backend. The install is the same as on Linux, with PyTorch from PyPI:
git clone --depth 1 --branch v0.36.0 https://github.com/Comfy-Org/ComfyUI.gitcd ComfyUIpython3.13 -m venv .venvsource .venv/bin/activatepip install torch==2.13.0 torchvision==0.28.0 torchaudiopip install -r requirements.txtpython main.pyThe course’s CI runs these commands on a macOS runner and uses the CPU only. Rendering SDXL on an M-series GPU is to verify: the README recommends a nightly PyTorch for Apple Silicon.
When the server is ready, its log ends with To see the GUI go to: http://127.0.0.1:8188. It listens on 127.0.0.1 only. The --listen flag opens it to the network, but the server has no login among its startup flags: anyone who reaches the port can queue work, upload files and read your outputs.
The course reuses a portable build that was already on the machine, without changing it. So it starts the server with its own base directory, which holds the input, output, temp, user and custom node folders, and it keeps the model folder of the install:
.\python_embeded\python.exe -s ComfyUI\main.py --base-directory D:\comfy-course ` --models-directory .\ComfyUI\models --database-url sqlite:///:memory: --disable-auto-launch--database-url sqlite:///:memory: keeps the server’s small asset database in memory instead of in the user folder. Two surprises came up with --base-directory at v0.36.0:
- The server stopped at startup with
FileNotFoundErrorwhen the base directory had nocustom_nodesfolder, because it lists that folder before loading anything (main.py, lines 198 to 201). Creating the empty folder is enough. - The flag moves the models folder too, unless
--models-directorypoints elsewhere.
On this machine the server answered in about 10 seconds. The start of its log says what it found:
Total VRAM 16303 MB, total RAM 65235 MBpytorch version: 2.13.0+cu130Set vram state to: NORMAL_VRAMDevice: cuda:0 NVIDIA GeForce RTX 5080 : cudaMallocAsyncDynamicVRAM support detected and enabledPython version: 3.13.14 (tags/v3.13.14:fd17997, Jun 10 2026, 13:03:48) [MSC v.1944 64 bit (AMD64)]ComfyUI version: 0.36.0comfyui-frontend-package version: 1.52.7Starting server
To see the GUI go to: http://127.0.0.1:8188
A model, and its license
Section titled “A model, and its license”ComfyUI ships no model. A diffusion checkpoint is one file that holds three networks, which lesson 2 explains: a denoising network, one or more text encoders, and a VAE. This course starts with Stable Diffusion XL base 1.0, published by Stability AI in July 2023. It is old by 2026 standards, but it runs in 16 GB, needs no account to download, and is what most tutorials and custom nodes were first written for. Lesson 8 compares it with recent models.
| File | Size | SHA-256 |
|---|---|---|
sd_xl_base_1.0.safetensors |
6,938,078,334 bytes | 31e35c80fc4829d14f90153f4c74cd59c90b779f6afe05a74cd6120b893f7e5b |
Put it in models/checkpoints/, and check its hash with certutil -hashfile <file> SHA256 on Windows, sha256sum on Linux, or shasum -a 256 on macOS; the file on this course’s machine matched. The safetensors format holds tensors and a JSON header, and no code, unlike older .ckpt files, which are Python pickles that can run code when loaded. The server log says Checkpoint files will always be loaded safely.
The model is under the CreativeML Open RAIL++-M License. A RAIL license gives broad rights to use and share the model and its outputs, and adds use restrictions listed in an attachment. Read it before you use the model in a product: this course doesn’t interpret it. The model card adds its own limits: “The model does not achieve perfect photorealism”, “The model cannot render legible text”, and “Faces and people in general may not be generated properly.” The course’s images contain no real people and no brands.
No model file is in the repository: the course’s CI uses workflows that need none.
The text-to-image graph
Section titled “The text-to-image graph”The simplest graph that makes an image has seven nodes:
flowchart LR ckpt["Load Checkpoint<br/>CheckpointLoaderSimple"] pos["Positive prompt<br/>CLIPTextEncode"] neg["Negative prompt<br/>CLIPTextEncode"] latent["Empty Latent Image<br/>1024 × 1024"] sampler["KSampler<br/>seed, steps, cfg"] decode["VAE Decode"] save["Save Image"] ckpt -- MODEL --> sampler ckpt -- CLIP --> pos ckpt -- CLIP --> neg ckpt -- VAE --> decode pos -- CONDITIONING --> sampler neg -- CONDITIONING --> sampler latent -- LATENT --> sampler sampler -- LATENT --> decode decode -- IMAGE --> save| Node | What it does | Outputs |
|---|---|---|
CheckpointLoaderSimple |
reads the checkpoint file and splits it into its three networks | MODEL, CLIP, VAE |
CLIPTextEncode, twice |
turns a prompt into vectors the model is conditioned on: what you want, and what you don’t | CONDITIONING |
EmptyLatentImage |
makes a blank latent image, a tensor of zeros one eighth of the image size | LATENT |
KSampler |
adds noise from the seed, then removes it step by step, guided by the prompts | LATENT |
VAEDecode |
decodes the latent into pixels | IMAGE |
SaveImage |
writes a PNG to the output folder | none: it is an output node |
The types in capitals are how the frontend knows what can connect to what. A LATENT output only plugs into a LATENT input, the way a compiler checks argument types. SaveImage is an output node: when you queue the graph, the server starts from the output nodes and works back through their inputs. A node that no output needs doesn’t run.
A first image, with curl
Section titled “A first image, with curl”In the browser, you would load this graph from the templates, type a prompt, and press Run. The API does the same thing without the browser. The course’s file workflows/01-txt2img.api.json describes the seven nodes in the API format: one entry per node, keyed by an id, with its type and its inputs. An input is either a value, or a link written ["4", 1], which means output 1 of node 4:
"3": { "class_type": "KSampler", "inputs": { "seed": 42, "steps": 25, "cfg": 7.0, "sampler_name": "euler", "scheduler": "normal", "denoise": 1.0, "model": ["4", 0], "positive": ["6", 0], "negative": ["7", 0], "latent_image": ["5", 0] } },To queue it, post it under a prompt key:
$workflow = Get-Content code\comfyui\workflows\01-txt2img.api.json -Raw$body = '{"prompt": ' + $workflow + '}'Invoke-RestMethod -Method Post -Uri http://127.0.0.1:8188/prompt -ContentType application/json -Body $bodycurl -s -X POST http://127.0.0.1:8188/prompt -H 'Content-Type: application/json' \ -d "{\"prompt\": $(cat code/comfyui/workflows/01-txt2img.api.json)}"curl -s -X POST http://127.0.0.1:8188/prompt -H 'Content-Type: application/json' \ -d "{\"prompt\": $(cat code/comfyui/workflows/01-txt2img.api.json)}"The server checks the graph, puts it in its queue, and answers at once, before anything runs:
{"prompt_id": "fbbda761-f93f-4d80-9403-0a5d47fc3306", "number": 0, "node_errors": {}}number is the position in the queue. When the prompt has run, GET /history/<prompt_id> returns what it produced; here, trimmed:
"outputs": {"9": {"images": [{"filename": "metronome_00001_.png", "subfolder": "l01", "type": "output"}]}},"status": {"status_str": "success", "completed": true, "messages": [ ["execution_start", {"prompt_id": "fbbda761-…", "timestamp": 1789575897123}], ["execution_cached", {"nodes": [], "prompt_id": "fbbda761-…", "timestamp": 1789575897124}], ["execution_success", {"prompt_id": "fbbda761-…", "timestamp": 1789575911832}]]}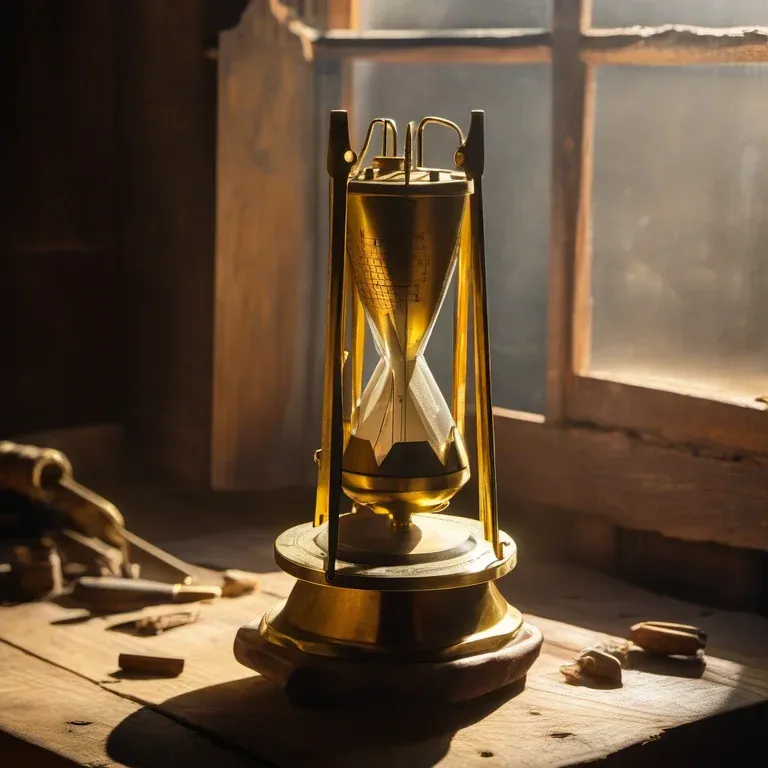
Rendered by ComfyUI v0.36.0: Stable Diffusion XL base 1.0, seed 42, 25 steps, euler sampler, normal scheduler, CFG 7, 1024 × 1024, workflow 01-txt2img.api.json, reduced to 768 × 768 for this page.
The prompt asked for “a brass metronome on an old wooden workbench”. SDXL drew something closer to an hourglass. The image is still a correct result: the model makes what its training data associates with the words, and a metronome is a rare object. Lesson 2 changes the seed and the settings: with seed 43, the object comes closer to a metronome.
What the time goes to
Section titled “What the time goes to”The log shows how the server spent the 14.71 seconds of this first run:
Requested to load SDXLClipModelModel SDXLClipModel prepared for dynamic VRAM loading. 1560MB Staged. 0 patches attached. Force pre-loaded 180 weights: 400 KB.Requested to load SDXLModel SDXL prepared for dynamic VRAM loading. 4896MB Staged. 0 patches attached. Force pre-loaded 512 weights: 1197 KB.100%|##########| 25/25 [00:03<00:00, 6.39it/s]Requested to load AutoencoderKLModel AutoencoderKL prepared for dynamic VRAM loading. 159MB Staged. 0 patches attached. Force pre-loaded 112 weights: 91 KB.Prompt executed in 14.71 secondsThe two text encoders take 1.5 GB, the denoising network 4.9 GB, and the VAE 159 MB. The 25 steps themselves took about 4 seconds, at 6.4 steps per second, after a 6.5-second first step in which the model was initialized. The rest went to reading the 6.9 GB file and moving weights to the GPU.
| Run | Time |
|---|---|
| First run after the server started | 14.71 s, then 12.99 s and 13.30 s after two restarts |
| Same graph, new seed: only the sampler, the decoder and the save run again | 4.53 to 4.89 s |
Same graph, only the file name prefix changed: only SaveImage runs |
0.07 to 0.09 s |
The last line is the cache at work: the history says "execution_cached": {"nodes": ["4", "5", "6", "7", "3", "8"]}, and SaveImage writes the cached image under its new name. When nothing at all has changed, even SaveImage is in the list, and no new file is written.
Where the image went
Section titled “Where the image went”SaveImage wrote output/l01/metronome_00001_.png: the prefix l01/metronome gives a subfolder and a name, and the server adds a five-digit counter. The PNG also holds the prompt that made it. The course’s C# tool lists the file’s chunks:
> dotnet out/csharp/comfy.dll png-info output/l01/metronome_00001_.pngchunk IHDR: 1 x, 13 byteschunk tEXt: 1 x, 921 byteschunk IDAT: 23 x, 3146752 bytes once inflatedchunk IEND: 1 x, 0 bytestext prompt: 914 characters: {"4": {"class_type": "CheckpointLoaderSimple", "inputs": {"c...image: 1024 x 1024, 3 channels, pixel SHA-256 698e7867e7fc04fbThe tEXt chunk named prompt holds the API-format graph as JSON: open the PNG in ComfyUI’s frontend, and it rebuilds the graph. Lesson 3 reads both chunks, and explains why a PNG saved from the browser has a second one.
Key takeaways
Section titled “Key takeaways”- ComfyUI is a Python server that runs graphs of typed nodes, and a browser frontend that edits them. The API takes the same graphs as the browser.
- The server runs only what an output node needs, and caches node results: an unchanged graph runs in a tenth of a second.
- The Windows portable build is one archive. On Linux and macOS, ComfyUI is a Python application in a virtual environment.
- A checkpoint holds a denoising network, text encoders and a VAE. SDXL base 1.0 is 6.9 GB, under the CreativeML Open RAIL++-M License, and draws what its training data suggests, not always what you asked for.
- The server has no authentication: keep it on 127.0.0.1.
Your turn
Section titled “Your turn”Get your own machine to the same place, then make it say so. Start the server, queue the lesson’s graph with curl, and read the three numbers this lesson read: how long the first image took, how long the second took with the models already loaded, and how much memory nvidia-smi showed while it sampled. Then change the prompt to something you care about — an object on your desk — and keep the first image you get, however wrong it is. Lesson 2 explains why it is wrong, and the comparison only means something if you have your own before.
Exercises
Section titled “Exercises”- Queue the lesson’s workflow twice with the same inputs, then once with
"seed": 43. Compare the three entries of/history: which nodes ran each time? GET /object_info/EmptyLatentImagereturns the declaration of a node. What are the minimum size and the step ofwidth, and why would a latent image need a step?- Change the negative prompt to an empty string and queue the workflow. Which nodes run again, and why does
CLIPTextEncodenode 6 not?
Solution 1
The first run has "execution_cached": {"nodes": []}: every node ran. The second lists all seven nodes, SaveImage included, and writes no new file: its outputs name the same metronome_00001_.png as the first run. The third lists nodes 4, 5, 6 and 7: the checkpoint, the empty latent and both prompts are reused, and KSampler, VAEDecode and SaveImage run, because the seed is an input of KSampler and the other two come after it in the graph.
Solution 2
"width": ["INT", {"default": 512, "min": 16, "max": 16384, "step": 8, "tooltip": "The width of the latent images in pixels."}]The minimum is 16 and the step 8. The node creates a tensor of width // 8 by height // 8 (nodes.py, line 1265): the VAE encodes 8 pixels into one latent position, so a width that isn’t a multiple of 8 would be cut. The server’s own max, 16384, is MAX_RESOLUTION; the /object_info answer gives the number, not the name.
Solution 3
Node 7, the negative prompt, runs again because its text input changed, and so do KSampler, VAEDecode and SaveImage, which depend on it. Node 6 has the same inputs as before, the same text and the same link to node 4’s CLIP, so the server reuses its cached output. A node’s cached result is reused when its own inputs, and those of the nodes it depends on, are unchanged.
Sources
Section titled “Sources”- ComfyUI at v0.36.0:
nodes.py,main.py,comfy/cli_args.py, README, release v0.36.0. - ComfyUI documentation: Windows portable, manual install, system requirements, text to image, server routes.
- Stable Diffusion XL base 1.0 model card and license; D. Podell et al., SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis, 2023.